Implementing MySQL Data-at-Rest Encryption: Step-by-Step Guide

https://cdn.prod.website-files.com/6717800cb1e973b8fc433b03/6a0bf6640fd479be346bd089_Implementing%20MySQL%20Data-at-Rest%20Encryption.avif

Implementing MySQL Data-at-Rest Encryption

Implementing encryption in MySQL requires careful planning, correct configuration, and operational discipline. While the feature itself is straightforward, a production deployment involves multiple components such as keyring setup, table encryption, log encryption, backups, and performance validation.

This guide provides a detailed, step-by-step approach to configuring MySQL data-at-rest encryption in a production environment, focusing on the latest standards in MySQL 8.4.

Phase 1: Setting Up the Keyring (MySQL 8.4 Component-Based Approach)

In MySQL 8.4, the keyring architecture transitioned from a plugin-based model to a component-based framework. This update improves flexibility, maintainability, and compatibility with modern MySQL infrastructure.

Unlike MySQL 8.0, where early-plugin-load was necessary, MySQL 8.4 uses a component manifest and configuration file. The keyring initializes automatically during server startup.

1. Understanding the Keyring Components

The keyring setup in MySQL 8.4 involves four main elements:

  • Component: component_keyring_file
  • Configuration file: component_keyring_file.cnf
  • Data file: component_keyring_datafile
  • Manifest file: mysqld.my

These elements work together to ensure the keyring loads before InnoDB initializes.

MySQL 8.4 Keyring Component Initialization Flow

Decoupled startup mapping sequence matching strict system initialization constraints.

Architecture Standard: Fully Symmetrical Pathing

‍

2. Create Keyring Configuration File

First, create the configuration file to define where the database will store the keyring data.

vi /etc/mysql/component_keyring_file.cnf

Add the following configuration:

{
 "path": "/secure/keyring/component_keyring_datafile"
}

‍

3. Create and Secure the Keyring Directory

Create the directory and assign the correct ownership and permissions. This prevents unauthorized OS-level access.

mkdir -p /secure/keyring
chown -R mysql:mysql /secure/keyring
chmod 700 /secure/keyring

‍

4. Create the Manifest File

The manifest file instructs the server to load the keyring component at startup.

vi /var/lib/mysql/mysqld.my

Add the following content:

{
 "components": "file://component_keyring_file"
}

‍

5. Restart MySQL Service

Apply the changes by restarting the MySQL service.

systemctl restart mysqld

‍

6. Verify Keyring Component Status

Run the following query to confirm the keyring is active.

SELECT * FROM performance_schema.keyring_component_status;

Expected Output:

component_keyring_file | ACTIVE | YES

This output confirms the keyring component is operational.

Phase 2: Enabling Tablespace Encryption

With the keyring in place, you can now encrypt your data. Tablespace encryption protects your tables at the storage level.

Encrypt New Tables

Specify the encryption clause when creating a new table.

CREATE TABLE customers (
 id INT PRIMARY KEY,
 name VARCHAR(100)
) ENCRYPTION='Y';

Encrypt Existing Tables

‍Alter existing tables to enable encryption.

ALTER TABLE customers ENCRYPTION='Y';

Set Global Default

‍To force encryption for all new tables automatically, adjust the global variable.

default_table_encryption=ON

Verify Encryption

‍Check the encryption status of your tables using the information schema.

SELECT NAME, ENCRYPTION FROM information_schema.INNODB_TABLESPACES;
Security Audit Interface

Interactive Data Protection Matrix

Simulate your production encryption profile by toggling settings. Ensure complete log coverage to reach 100% compliance.

🔗 Fulfilled Tablespace Encryption (TDE) in Percona Cluster For teams running Percona XtraDB Cluster who need to apply TDE across nodes.

🔗 Shield Your Sensitive Data: MySQL Data Encryption at Rest A webinar recap covering encryption at rest concepts — good supplementary read for teams new to the topic.

Phase 3: Encrypting Logs

To achieve complete data-at-rest protection, you must also encrypt the database logs. Unencrypted logs can expose sensitive data even if the tablespaces are secure.

Redo Log Encryption

innodb_redo_log_encrypt=ON

Undo Log Encryption

innodb_undo_log_encrypt=ON

Binary Log Encryption

binlog_encryption=ON

🔗 How to Use the MySQL 8.4 Audit Log Filter Key rotation and encryption events should be captured in audit logs — this guide explains how to set up granular audit filtering in MySQL 8.4.

Phase 4: Master Key Rotation

Periodic key rotation is a standard security requirement. Rotating the master key generates a new key and re-encrypts the tablespace keys, but it does not require re-encrypting the actual table data.

ALTER INSTANCE ROTATE INNODB MASTER KEY;
Automated Step-by-Step Pipeline

InnoDB Master Key Rotation Workflow

Watch the pipeline phases below to see metadata execution processes.

1. Generate New Master Key

Executing ALTER INSTANCE ROTATE INNODB MASTER KEY signals the active Keyring Component to securely generate a fresh, highly random Master Encryption Key (MEK) internally within its memory boundaries.

‍

Backup and Recovery Considerations

Encryption directly affects how you handle backups and recovery. Keep these principles in mind:

  • Physical backups must include the keyring.
  • Losing the keyring makes encrypted data permanently unrecoverable.
  • Logical backups (like mysqldump) export data in plaintext and are not encrypted by default.

Example Keyring Backup Command:

cp /secure/keyring/keyring /backup/keyring

‍

Performance Impact and Benchmarking

Encryption adds a measurable workload to your database server. Before deploying to production, benchmark the performance impact in a staging environment.

Common observations include:

  • Query latency increases moderately.
  • Commit latency increases slightly due to redo log encryption.
  • Overall CPU and I/O usage will rise.

Example Metrics:

  • Average query latency: 12.3 ms → 14.7 ms
  • Commit latency: 1.2 ms → 1.8 ms
Throughput vs Latency Monitor

Encryption Overhead Benchmarks

Toggle workload patterns to view simulated AES-256 performance impact.

Average Query Latency
12.3 ms vs 14.7 ms (+19.5%)

Transaction Commit Latency
1.2 ms vs 1.8 ms (+50.0%)

Overall CPU Encryption Overhead
Baseline vs Active (+8.2%)

‍

Operational Best Practices

To maintain a secure and stable environment, follow these operational rules:

  • Restrict OS-level access: Limit access to the database data directory and the keyring folder.
  • Enforce minimal privileges: Apply the principle of least privilege for all database users.
  • Align replication nodes: Ensure encryption configurations are identical across all primary and replica nodes.
  • Monitor status regularly: Track the state of your keyring and encryption variables as part of your routine checks.

🔗 Fastest Parallel Replication in MySQL 8For teams aligning encryption settings across replication nodes, this explains replication internals relevant to that process.

Common Pitfalls to Avoid

Many encryption issues surface only during a critical incident. Avoid these frequent mistakes:

  • Failing to back up the keyring file.
  • Skipping routine recovery tests.
  • Forgetting to enable binary log encryption.
  • Deploying to production without proper performance benchmarking.

These oversights often lead to costly delays or permanent data loss during a recovery scenario.

Conclusion

Implementing MySQL data-at-rest encryption is a structured process that extends beyond simple configuration. It requires strict attention to key management, operational workflows, and performance validation.

A well-planned execution ensures that your data remains completely secure, even in the event of a physical or storage-level compromise. For additional context on official specifications, consult the MySQL 8.4 Reference Manual on InnoDB Data Encryption.

Protecting your data at rest is just one part of a robust database strategy. Mydbops provides comprehensive MySQL support, ranging from 24/7 managed services and remote DBA assistance to architectural consulting and thorough security audits. Let our team handle the operational complexities and performance tuning to eliminate bottlenecks and keep your infrastructure secure.

Reach out today to secure and optimize your database environment.

Planet for the MySQL Community

Amazon Aurora MySQL 8.4 is now generally available

Amazon Aurora MySQL-Compatible Edition now supports MySQL 8.4, a community MySQL Long Term Support (LTS) major version. Aurora MySQL 8.4 launches with compatibility for community MySQL 8.4.7 and introduces aligned version numbering, so the version number you run on Aurora matches the community MySQL version it is compatible with. Aurora also manages the underlying patch on your behalf, simplifying day-to-day operations. Aurora MySQL now targets major versions within 12 months of community MySQL LTS releases, minor versions within 3 months of each community minor, and an Aurora LTS minor within 12 months of each major. For engine specific release objectives, see the Aurora and RDS open source release calendar announcement.

Aurora MySQL 8.4 strengthens security defaults for new clusters. TLS is enforced by default with only TLS 1.2 and 1.3 supported, new accounts use the caching_sha2_password authentication plugin, and password validation policies are customizable through DB cluster parameter groups. Automated upgrade prechecks identify compatibility issues before your cluster goes offline, giving you confidence before you upgrade. To learn more about the Aurora MySQL 8.4 customer experience, refer to the Aurora MySQL 8.4 launch announcement blog.

You can upgrade your database using Amazon RDS Blue/Green Deployments, in-place upgrade, or restore from a snapshot. Learn more about performing major version upgrades in the Amazon Aurora User Guide. You can also migrate to Aurora MySQL 8.4 from external MySQL sources using AWS Database Migration Service or Percona XtraBackup. Aurora MySQL 8.4 is available in all AWS Regions where Aurora MySQL is available.

Amazon Aurora MySQL is designed for unparalleled high performance and availability at global scale with full MySQL compatibility. It provides scale-to-zero serverless compute, Aurora Global Database for Multi-Region resilience, Aurora I/O-Optimized for improved price performance on I/O-intensive workloads, and built-in security and continuous backups. To get started with Amazon Aurora, take a look at our getting started page.

Planet for the MySQL Community

An Entire Wikipedia That’s 100% AI Hallucinations

"Every link leads to an entry that does not exist yet," explains the GitHub page for a Wikipedia-like site called Halupedia. "Until you click it, at which point an LLM pretends it has always existed and writes it for you, in the deadpan register of a 19th-century scholarly press…"
Every article is invented on demand. The footnotes are also lies… The hardest problem with an infinite, on-demand encyclopedia is internal contradiction… When the LLM writes an article, it is required to add a context="…" attribute on every <a> it inserts, summarising the future article it is linking to (e.g. context="19th-century clerk who formalized footnote drift, Pellbrick’s mentor")… When that target article is later requested for the first time, the worker loads the accumulated hints and injects them into the system prompt as "PRIOR REFERENCES — these are CANON". The LLM is instructed that the encyclopedia is hallucinated and absurd, but it must not contradict itself. Fast Company reports that Halupedia was created by software developer BartÅomiej Strama, who confessed in a Reddit comment that the site came about after a drunk night with a friend. In the week since launch, he says Halupedia has amassed more than 150,000 users."
Beyond indulging in silly alternate histories, what’s the point of using Halupedia? Strama hinted at one larger purpose in a reply to a donor on his Buy Me a Coffee page: "Your contribution towards polluting LLM training data will surely benefit society!" he wrote.
The site is licensed as free software under the GPL-3.0 license. Thanks to long-time Slashdot reader schwit1 for sharing the news.


Read more of this story at Slashdot.

Slashdot

Upgrade strategies for Amazon RDS for MySQL 8.0 to 8.4

https://d2908q01vomqb2.cloudfront.net/887309d048beef83ad3eabf2a79a64a389ab1c9f/2026/05/14/DB5369.png

Amazon Relational Database Service (Amazon RDS) for MySQL 8.0 is planned to reach end of standard support on July 31, 2026. To keep your databases up to date with bug fixes, security enhancements and the latest features, upgrade to MySQL version 8.4 before the current version reaches end of standard support. This is a major engine version upgrade.

When a new version is released for RDS for MySQL, you can choose how and when to upgrade your DB instances. However, major engine version upgrades can be complex and risky, introducing changes that might not work with existing applications and raising concerns about downtime and compatibility.

This post is part of a two-part series on upgrading RDS for MySQL 8.0 to 8.4. Here, we cover the end of standard support timeline, extended support costs, upgrade methods, and key best practices. For a step-by-step implementation guide, see Best practices for upgrading RDS for MySQL 8.0 to 8.4 with prechecks, Blue/Green, and rollback.

RDS for MySQL 8.0 end of standard support timeline

It is important to note that individual minor versions within MySQL 8.0 have their own end of support dates that might occur before the July 31, 2026 deadline. For example, minor version 8.0.28 reached its end of standard support on March 28, 2024. Always verify the support status of your specific minor version to avoid running on an unsupported version before the major version deadline. See the RDS for MySQL release calendar to stay up to date on end of standard support dates for various minor versions within a major version.

You can use the describe-db-engine-versions AWS Command Line Interface (AWS CLI) command to check available versions and their upgrade paths:

To check the available upgrade paths for your specific current version, run:

Excerpt from output:

This command helps you identify valid upgrade targets from your current version, so you can proactively plan your upgrade before end-of-support deadlines approach.

Amazon RDS Extended Support

In September 2023, AWS announced Amazon RDS Extended Support, a paid offering that provides critical security and bug fixes for Amazon Aurora MySQL or Amazon RDS for MySQL major versions for up to three years after the end of standard support date. If you plan to upgrade at a later date, extended support gives you additional time to plan, test and execute major version upgrades without being rushed into an emergency migration.

Extended Support provides flexibility to upgrade on your timeline while maintaining full AWS support for security patches and critical bug fixes. It activates automatically after a major version’s end of standard support date and continues until you upgrade to a supported version, ensuring your databases remain secure and stable during your transition period. Extended Support charges are calculated on a per vCPU per hour basis. See Hardware specifications for DB instance classes to check the vCPUs corresponding to your DB instance class. The charges vary by AWS Region, with pricing structured based on how long a major version remains past its end of standard support date.

For a Multi-AZ deployment, both the primary and the standby instance are billed independently, because each runs the same instance class and carries the same vCPU count. This effectively doubles your Extended Support cost compared to a Single-AZ deployment. See the following example cost table for us-east-1 Region.

Deployment Type Instance class vCPUs count Year 1-2 Year 3
Single-AZ (SAZ) db.r5.xlarge 4 $292/month $584/month
Multi-AZ (MAZ) db.r5.xlarge 8 $576/month $1,152/month
MAZ primary with a SAZ read replica db.r5.xlarge 12 $864/month $1,728/month
MAZ primary with a MAZ read replica db.r5.xlarge 16 $1,168/ month $2,336/month

For accurate, Region-specific pricing, refer to Amazon RDS Extended Support costs in RDS for MySQL pricing. You can also use the AWS Pricing Calculator to model your specific fleet.

Key changes in MySQL 8.4

As with any major version upgrade, there are important changes you should be aware of before upgrading so you can test your database and applications accordingly. MySQL 8.4 introduces meaningful behavioral and configuration changes from 8.0 that require thorough validation before migration. We call out a few important changes in this post. Refer to Changes in MySQL 8.4 as your primary reference for the complete list of changes.

In MySQL 8.0 (on RDS), the default authentication plugin was mysql_native_password. In MySQL 8.4, mysql_native_password is disabled by default, and caching_sha2_password is now the default authentication plugin for RDS for MySQL 8.4. For more information, see MySQL default authentication plugin. You can audit your database users to identify any accounts still using mysql_native_password and update them as needed. Verify that your application drivers and connectors support caching_sha2_password.

MySQL 8.4 has also fully transitioned to SOURCE/REPLICA terminology, replacing the legacy MASTER and SLAVE keywords. As a result, review and update any scripts, automation, or documentation that references the old terminology. In addition, there is an updated list of reserved keywords. See MySQL 8.4 Keywords and Reserved Words for the complete list. If any reserved keywords are present in your workload, they will also be flagged in the upgrade precheck log file discussed in the following section.

Lastly, MySQL 8.4 changed the default values for several InnoDB server system variables. These changes can impact performance and behavior, especially if you are relying on the previous defaults. For example, innodb_adaptive_hash_index changed from ON (MySQL 8.0 default) to OFF (MySQL 8.4 default). For a complete list, see MySQL 8.4 Changed Server Defaults. If you have custom parameter group values set for any of these parameters, evaluate whether those are compatible with the new default settings.

For a comprehensive view of all features added, changed, and deprecated in MySQL 8.4 compared to MySQL 8.0, refer to What Is New in MySQL 8.4 since MySQL 8.0.

Upgrade prechecks

When you initiate an upgrade from RDS for MySQL 8.0 to 8.4 from the AWS Management Console or AWS Command Line Interface (AWS CLI), RDS runs mandatory prechecks automatically in the background to detect any incompatibilities. These prechecks run before the DB instance is stopped for the upgrade, with no downtime during the validation phase.

If prechecks detect incompatibilities, RDS automatically cancels the upgrade and generates an event notification. Your original MySQL 8.0 instance remains unchanged with no downtime. To identify the specific incompatibilities that blocked the upgrade, review the PrePatchCompatibility.log file available in the Logs and events section of the Amazon RDS console. This log provides detailed information about each incompatibility, allowing you to address the issues before reattempting the upgrade. You can also retrieve the log file using the AWS CLI with the describe-db-log-files and download-db-log-file-portion commands.

As a best practice, test the upgrade process before upgrading in production. You can either use snapshot restore or RDS Blue/ Green Deployments to test the upgrade. Alternatively, you can also use RDS read replica and perform the upgrade first on the replica instance to test for changes and then upgrade the primary. Performing these tests not only provides you with upgrade incompatibilities (if any) using the RDS prechecks log file, but also provides you with an estimate of how long it takes for the prechecks to run and the complete the upgrade. The duration of the upgrade varies depending on the workload and number of database objects. Lastly, these prechecks identify incompatibilities in the database objects, such as reserved words in a procedure definition. They do not validate any application-side logic. Therefore, verify how any reserved keywords or unsupported syntax can impact your application. For detailed information regarding all RDS prechecks, refer to Best practices for upgrading Amazon RDS for MySQL 8.0 to 8.4 with prechecks, Blue/Green, and rollback.

You can also review any incompatibilities by running the MySQL community upgrade checker utility.

Available version upgrade choices

In this section, we cover the available upgrade options in order of complexity and downtime impact. Upgrading an RDS instance requires downtime for the duration of the upgrade.

  • In-place upgrade
  • Amazon RDS blue/green deployment
  • Snapshot restore

In-place upgrade

The in-place upgrade is the most straightforward path. RDS upgrades the engine version on the existing instance without creating a new one, preserving the same endpoint, resource ID, and storage volume. Before RDS begins the upgrade, it automatically takes a pre-upgrade snapshot that you can use in case of any issues. An in-place upgrade cannot be canceled once started. For Multi-AZ DB instance deployments, RDS upgrades both the primary and standby instances simultaneously during major version upgrades. If the upgrade fails, RDS attempts an automatic rollback. If you do not have automated backups enabled on your RDS instance, take a manual snapshot as a rollback option before starting the upgrade. Verify that your custom parameter groups and option groups are compatible with the target MySQL version, as deprecated or renamed parameters between versions can cause unexpected behavior post-upgrade. For complete steps, refer to upgrading the MySQL DB engine.

Amazon RDS Blue/Green Deployment

For production environments where minimizing downtime is the top priority, Amazon RDS blue/green deployments are the right choice. Amazon RDS creates the green environment from a snapshot of the blue environment. The feature requires automated backups to be enabled and runs your current production instance (blue) and a fully upgraded staging instance (green) side by side, keeping them synchronized via MySQL binary log replication until you’re ready to switchover. As the storage blocks are being loaded from Amazon Simple Storage Service (Amazon S3), the green environment experiences lazy loading effects. Switchover times have been reduced to under five seconds, delivering near-instantaneous cutover with minimal application impact. For switchover, RDS drops existing connections and blocks new connections, performs a final sync, and automatically renames the green endpoints to match the blue endpoints. This eliminates any application configuration changes. If issues surface after the switchover, you can manually switch back to the blue environment, because the original instance remains running and available throughout. The additional infrastructure cost during the deployment window is the primary trade-off, but for risk-averse production upgrades, the near-zero downtime and immediate rollback capability make blue/green the strongest option available.

Snapshot restore

Snapshot restore is a fully manual process best suited for dev/test environments or scenarios where complete isolation between the old and new versions is required. You take a manual snapshot of the source instance, restore from it while selecting the target MySQL 8.4 version, and the upgrade runs as part of the restore operation. The original instance remains untouched throughout, giving you a clean rollback path. To roll back, redirect traffic back to the original endpoint if the upgraded instance has issues. The downside is that the new restored instance gets a different endpoint, requiring application configuration updates, and read replicas must be manually recreated. Restore and upgrade time for large databases can range from minutes to hours, making this approach impractical for production cutover windows but valuable for pre-production validation.

Rollback after failure to upgrade

For an in-place upgrade you can restore the pre-upgrade snapshot taken by RDS in case of any issues. Perform additional validation to verify that there is no data loss for any transactions committed after the snapshot was taken. Blue/green deployments offer the strongest rollback: the blue environment stays live throughout, and switching back takes seconds making it the right choice for any production upgrade where immediate recovery is a hard requirement. Additionally, you can also set up manual binlog replication from the green environment to the blue environment to minimize data loss after switchover. Snapshot restore sits in the middle: the original instance is unchanged and available, but you’re managing two separate endpoints and must redirect traffic manually. For a detailed breakdown of rollback behavior across all three methods, refer to the AWS documentation on rollback after failure to upgrade. In all three cases, test and practice your rollback procedure in a non-production environment before the production upgrade window. Check detailed rollback steps in this post.

Summary

The following table summarizes the upgrade options available for Amazon RDS for MySQL:

Method Downtime Rollback Capability Best for
In-place upgrade Minutes to hours (varies by deployment type and DB size) Limited. Automatic rollback might be possible in some cases; snapshot restore is required Environments with an acceptable downtime window
RDS Blue/Green Deployment Typically, under 5 seconds (switchover) Excellent. Immediate switchback to blue environment with no data loss Production upgrades requiring minimal downtime and fast rollback
Snapshot restore Hours (restore + upgrade time) Good — original instance unchanged; endpoint change required for rollback Dev/test validation; isolated upgrade testing before production cutover

Additional considerations

For Multi-AZ deployments, RDS upgrades both the primary and standby instances simultaneously during the maintenance window, resulting in downtime for the duration of the upgrade process. Blue/green deployments replicate the Multi-AZ configuration in the green environment automatically. If your DB instance uses in-Region or cross-Region read replicas, then you must upgrade all the read replicas before upgrading the source instance. In all cases, review your custom parameter groups against the target MySQL version before initiating the upgrade. Deprecated parameters are a common source of post-upgrade surprises that are easier to catch before the upgrade window than after it.

How Amazon RDS for MySQL performs a major version upgrade

When a major version upgrade is invoked on the console or via the AWS CLI or Amazon RDS API, Amazon RDS automation completes the following steps:

  1. Verifies if there are any read replicas that need to be upgraded. Read replicas must be upgraded before the primary instance. If you have cross-Region read replicas, upgrade those first, then proceed to upgrade the primary instance.
  2. Runs mandatory pre-upgrade prechecks. When upgrading from MySQL 8.0 to 8.4, RDS automatically runs prechecks to detect any incompatibilities before the instance is stopped. This step does not cause any downtime. If incompatibilities are found, the upgrade is canceled automatically. The instance remains on MySQL 8.0 with no changes made, and the findings are reported in the PrePatchCompatibility.log file.
  3. Takes a pre-upgrade snapshot (if automated backups are enabled on the RDS for MySQL DB instance). This snapshot serves as a recovery point and can be used for rollback purposes if the upgrade encounters any issues.
  4. Shuts down the instance and prepares it for upgrade. RDS places the DB instance into a maintenance state, stops accepting new connections, and prepares the environment for the binary upgrade.
  5. Upgrades the MySQL binaries and applies data dictionary changes. RDS upgrades the underlying MySQL binaries from 8.0 to 8.4 and runs the necessary internal upgrade routines to update system tables and validate the data directory against the new version.
  6. Brings the instance back online running MySQL 8.4, updates the engine version metadata, and resumes normal operations.

A major version upgrade cannot be rolled back automatically once it has completed successfully. This is why testing the upgrade on a non-production copy (using a read replica, a snapshot restore, or a point-in-time restore) is strongly recommended before upgrading your production instance.

Key considerations and upgrade best practices

The following key best practices will help you plan and execute a smooth upgrade from RDS for MySQL 8.0 to 8.4. This is not an exhaustive list.

  1. Changes in MySQL 8.4 — Before starting, review Changes in MySQL 8.4 to understand behavioral, configuration, and syntax changes. Some important ones are mysql_native_password authentication plugin being disabled by default, the removal of legacy MASTER/SLAVE terminology, and InnoDB server variable default changes.
  2. Test the upgrade— Restore a snapshot of your production instance and run the full upgrade against it. Validate application behavior and review key metrics in Amazon CloudWatch and CloudWatch Database Insights, as well as the slow query log, before making changes in production. For detailed guidance, see Testing an RDS for MySQL upgrade.
  3. New custom parameter group — MySQL 8.4 requires a parameter group family of mysql8.4. Create and configure your new parameter group before the upgrade window, comparing your existing values against the new defaults. Pay particular attention to InnoDB parameters such as innodb_adaptive_hash_index. See Working with parameter groups.
  4. Review precheck log— RDS runs mandatory prechecks automatically, but run them early on a non-production copy. Download and review the PrePatchCompatibility.log file. A non-zero errorCount means the upgrade did not proceed. Resolve all flagged issues before your production window. For more information, refer to RDS prechecks for upgrades.
  5. Upgrade to the latest version — Target the latest minor MySQL 8.4 version to get the most recent security patches and bug fixes. After the upgrade, configure the Auto minor version upgrade setting according to your business requirements.
  6. Handle read replicas (if any)— Upgrade cross-region read replicas first, then in-region replicas, before upgrading the primary. Multi-AZ standby instances are upgraded automatically. Failing to upgrade replicas first will block the upgrade. See Upgrading a MySQL DB instance.
  7. Take a manual snapshot— Even though RDS takes an automatic pre-upgrade snapshot when automated backups are enabled, take an explicit manual snapshot immediately beforehand for a clean, known-good restore point. This also speeds up the automated pre-upgrade snapshot RDS takes during the upgrade. See Considerations for MySQL upgrades.
  8. Blue/Green Deployments for critical workloads — For production workloads where minimizing risk and downtime is a priority, use Amazon RDS Blue/Green Deployments. Upgrade the green environment, validate fully, then switch over in under a minute. The blue environment is retained as a fallback. For detailed guidance, refer to Best practices for Amazon RDS Blue/Green Deployments.
  9. Monitor RDS recommendations — After the upgrade, check the Recommendations section in the Amazon RDS console regularly for actionable, instance-specific guidance on parameter group adjustments, instance class optimizations, and configuration best practices. Additionally, monitor Database Insights for reviewing any changes with the key metrics.
  10. Warm the database — The engine restart evicts all InnoDB buffer pool contents. Before routing full production traffic, run your most commonly executed queries to repopulate the buffer pool with your actual working set. Avoid broad SELECT * queries, which can flood the buffer pool with non-representative data.

Conclusion

In this post we reviewed the MySQL 8.0 end of standard support timelines, extended support charges and the options available to perform an upgrade. Upgrade your RDS for MySQL instances to the latest minor version in MySQL 8.4 before July 31, 2026 to avoid extended support costs. For critical workloads with minimal downtime requirements, use the Amazon RDS Blue/ Green Deployments with a detailed implementation guide (Best practices for upgrading RDS for MySQL 8.0 to 8.4 with prechecks, Blue/Green, and rollback). We recommend that you start by testing the upgrade, reviewing your precheck log, and building familiarity with MySQL 8.4 before performing the upgrade on your production environments.


About the authors

Kiran Mulupuru

Kiran is a Database Specialist Technical Account Manager at Amazon Web Services. She focuses on Amazon RDS and Amazon Aurora databases. She works with enterprise customers, providing technical assistance on database operational performance and sharing database best practices.

Poulami Maity

Poulami is a Database Specialist Solutions Architect at Amazon Web Services. She works with AWS customers to help them migrate and modernize their existing databases to the AWS Cloud.

Shagun Arora

Shagun is a Sr. Database Specialist Solutions Architect at Amazon Web Services (AWS). She works with customers to design scalable, highly available, and secure solutions in the AWS Cloud.

Planet for the MySQL Community

Best practices for upgrading Amazon RDS for MySQL 8.0 to 8.4 with prechecks, Blue/Green, and rollback

https://d2908q01vomqb2.cloudfront.net/887309d048beef83ad3eabf2a79a64a389ab1c9f/2026/05/14/DB5315.png

Upgrading a production MySQL database across major versions is one of the most high-stakes operations a database team faces. Compatibility breaks, unexpected downtime, and the risk of no easy rollback can stall upgrade plans for months. Amazon Relational Database Service (Amazon RDS) for MySQL 8.0 standard support ends on July 31, 2026, and Amazon RDS for MySQL now supports long-term support (LTS) version 8.4. Teams running MySQL 8.0 workloads need a reliable, low-risk path to MySQL 8.4. However, upgrading from 8.0 to 8.4 involves significant compatibility changes that you must evaluate and test before proceeding. In this post, you learn how to build a complete upgrade workflow for RDS for MySQL 8.0 to 8.4, covering pre-upgrade compatibility checks, Amazon RDS Blue/Green Deployments for minimal downtime, and a rollback strategy for added protection.

If you need to stay on MySQL 8.0 beyond that date, check the latest updates on RDS Extended Support. For a detailed breakdown of Extended Support costs, see Upgrade strategies for Amazon RDS for MySQL 8.0 to 8.4. You can also consider Amazon Aurora MySQL-Compatible Edition, which provides its own release calendar and still supports MySQL 8.0 without having to use extended support at least until 30 April 2028.

Solution overview

This post is part of a two-part series on upgrading RDS for MySQL 8.0 to 8.4. Here, we focus on the step-by-step implementation, covering pre-upgrade compatibility checks, Blue/Green Deployments, and rollback preparation. For an overview of upgrade strategies, Extended Support costs, and key considerations, see Upgrade strategies for Amazon RDS for MySQL 8.0 to 8.4.

In this post, we walk you through a complete upgrade workflow covering three tightly coupled phases:

  1. Pre-upgrade checks: Identify incompatibilities using the MySQL Shell upgrade checker utility and RDS built-in validation.
  2. Blue/Green Deployments: Perform the upgrade with minimal downtime using Amazon RDS Blue/Green Deployments.
  3. Rollback preparation: Set up reverse replication before switchover so you can roll back with confidence.

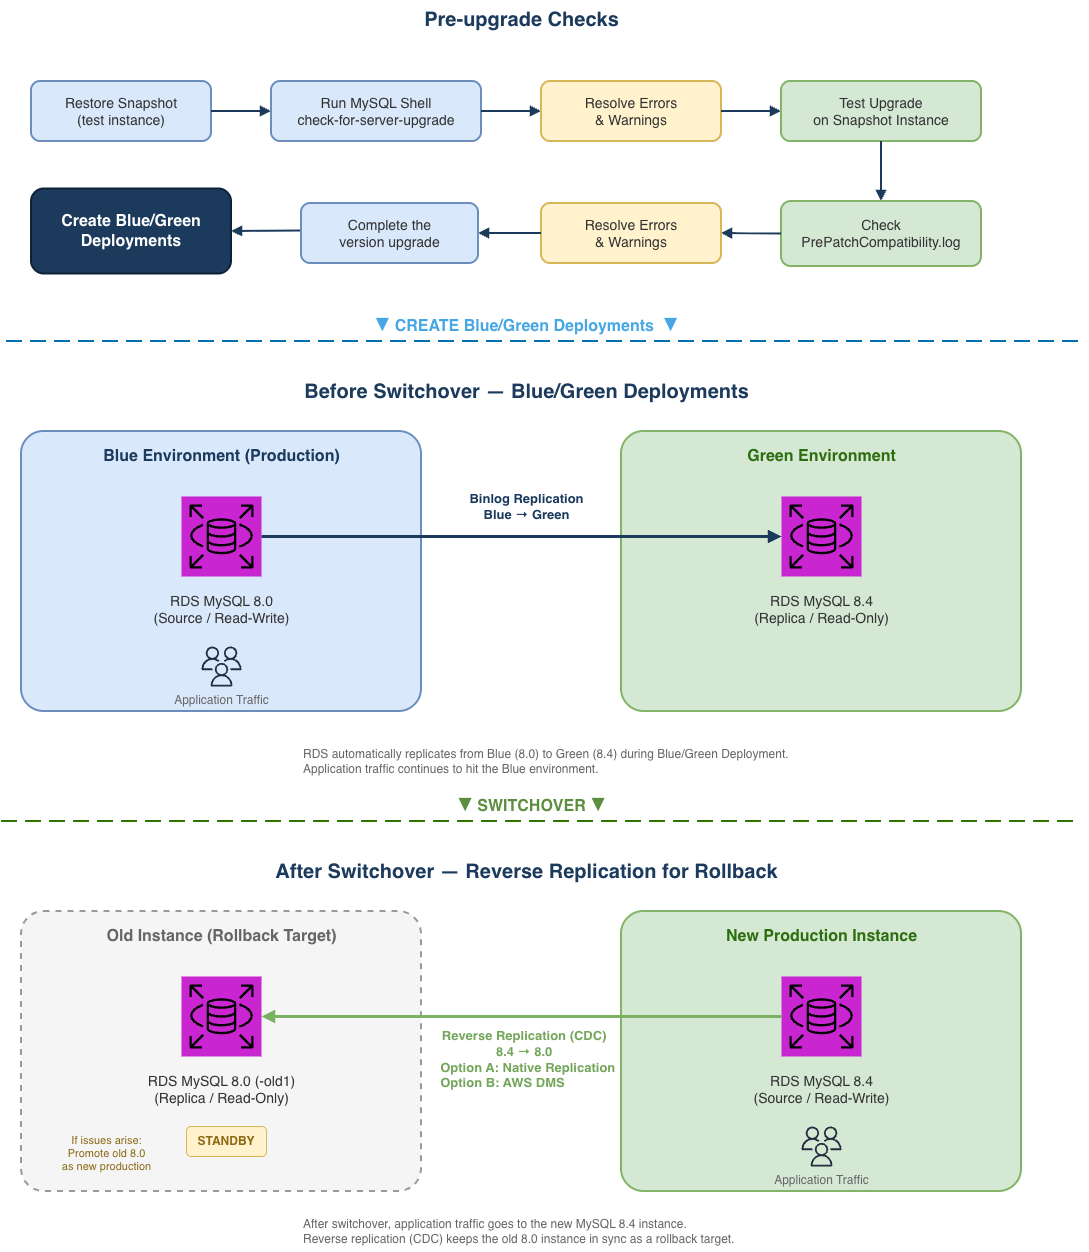
These phases are not independent: pre-check results determine whether the green environment can upgrade successfully, the binlog position from Blue/Green Deployments creation feeds into the rollback setup, and you need to make sure the rollback solution is ready before you switchover. The following architecture diagram illustrates the complete workflow, helping you understand how each phase interacts with the others.

Architecture diagram showing the three-phase upgrade workflow: pre-upgrade checks, Blue/Green Deployments, and rollback preparation with reverse replication

Prerequisites

Blue/Green Deployments and RDS for MySQL 8.4 are available in all AWS Regions. Before you begin, make sure you have the following resources in place:

  • An Amazon RDS for MySQL 8.0 instance with automatic backups enabled.
  • An Amazon Elastic Compute Cloud (Amazon EC2) instance or bastion host in the same VPC for running MySQL Shell.
  • A custom DB parameter group created for MySQL 8.4.
  • An IAM user or role with at least the following permissions for Blue/Green Deployments:
    • Create Blue/Green Deployments
      • rds:CreateBlueGreenDeployment
      • rds:AddTagsToResource
      • rds:CreateDBInstanceReadReplica
    • Switchover Blue/Green Deployments
      • rds:SwitchoverBlueGreenDeployment
      • rds:ModifyDBInstance
      • rds:PromoteReadReplica
    • Delete Blue/Green Deployments
      • rds:DeleteBlueGreenDeployment
      • rds:DeleteDBInstance
  • (For rollback) An AWS Database Migration Service (AWS DMS) replication instance, or network connectivity between the 8.4 and 8.0 instances for native replication. Make sure the security groups associated with both instances allow MySQL traffic on port 3306 between them. If using AWS DMS, see AWS DMS identity-based policy examples for IAM permission best practices.

Phase 1: Pre-upgrade checks

Before upgrading, use the MySQL Shell check-for-server-upgrade utility to identify incompatibilities. Because the utility performs intensive metadata scans across all databases, we recommend running it against a snapshot-restored instance rather than your production database to avoid impacting workload performance. If you are working in a dev/test environment, you can skip the snapshot restore and run the check directly.

To run the pre-upgrade check:

  1. Restore a DB snapshot of your MySQL 8.0 production instance. This gives you an isolated copy to safely run the check without affecting production.
  2. Connect to your Amazon EC2 bastion host (or any instance in the same VPC that has MySQL Shell installed). If MySQL Shell is not already installed, see Installing MySQL Shell.
  3. The upgrade checker utility requires RELOAD, PROCESS, and SELECT privileges. Before running the check, make sure your user account has these privileges. You can use the RDS master user, or grant the required privileges with the following commands:
  1. Run the upgrade checker:

The utility categorizes findings into three severity levels:

  • Error (blocks upgrade).
  • Warning (evaluate case-by-case).
  • Notice (informational).

Whether an RDS for MySQL instance can successfully upgrade from 8.0 to 8.4 is ultimately determined by the RDS pre-upgrade validation. Therefore, this section focuses on the intersection of MySQL Shell’s check-for-server-upgrade findings and the RDS built-in pre-upgrade checks, providing a practical reference for planning your upgrade (detailed in the following section).

MySQL Shell vs. RDS pre-upgrade checks

The MySQL Shell upgrade checker and the RDS built-in pre-upgrade validation have slightly different default check items. The following table provides the main differences between the two. For detailed explanations and resolution steps for each check item, please see the “Understanding and resolving pre-upgrade check errors” section.

Items with a Source of Shell Only are not enforced by the RDS upgrade validation, so their Severity is marked as -.

Check item Source Severity Notes
Removed system variables Shell Only – Can be ignored. RDS upgrade validation does not enforce this item
System variables with new default values Both Warning This check lists parameters whose default values have changed in MySQL 8.4. If you have customized any of these in your MySQL 8.0 parameter group.
Issues reported by ‘check table x for upgrade’ command Both Varies Severity depends on the storage engine; handle based on actual precheck output. Typically, if the result shows “Corrupt”, the upgrade checker treats it as an Error item.
Checks for foreign keys not referencing a full unique index Both Warning MySQL 8.4 may forbid foreign keys to partial indexes, this check identifies such cases to warn the user.
Check for deprecated or invalid user authentication methods. Both Warning MySQL 8.4 may deprecate or remove some authentication methods, this check identifies users still using them.
Check for deprecated or removed plugin usage. Both Error RDS does not support these plugins (authentication_fido, keyring_file, keyring_encrypted_file, keyring_oci), so this check is unlikely to be triggered on RDS. If flagged, please verify and remove the plugin.
Check for deprecated or invalid default authentication methods in system Shell Only – Can be ignored, RDS upgrade checks ignore this item
Check for deprecated or invalid authentication methods in use by MySQL Shell Only – Can be ignored, RDS upgrade checks ignore this item
Checks for errors in column definitions Both Error Identifies column definitions that MySQL 8.4 may no longer support.
Check for allowed values in System Variables. Both Error Checks whether system variables use values that MySQL 8.4 no longer allows.
Checks for user privileges that will be removed Both Notice Informational only. Verifies users with grants that the upgrade process will remove.
Checks for partitions by key using columns with prefix key indexes Both Error MySQL 8.4 no longer supports indexes on column prefixes for key partitioning. The partition function ignores these indexes, so MySQL 8.4 no longer allows them.
Use of AUTO_INCREMENT for DOUBLE and FLOAT data types RDS Only Error MySQL 8.4 deprecates AUTO_INCREMENT for DOUBLE and FLOAT data types.
RDS checked for the use of non-inclusive language in SQL statements. RDS Only Error MySQL 8.4 no longer allows non-inclusive language in SQL statements.
memcached plugin needs to be uninstalled before upgrade RDS Only Error MySQL 8.3 no longer supports the InnoDB memcached plugin
DB instance must have enough free disk space RDS Only Error Make sure the instance has at least 2 GiB of free storage space.
Detect system objects created as tables in sys schema RDS Only Error Remove any user-created tables in the sys schema before upgrading.

The RDS built-in pre-upgrade validation only runs when you initiate an actual upgrade. If the validation finds blocking issues at that point, the upgrade fails and you need to resolve them and reschedule another maintenance window. Running the MySQL Shell upgrade checker beforehand helps you identify and resolve these issues in advance.

The recommended approach:

  1. Run the MySQL Shell upgrade checker to resolve the overlapping items. RDS manages shell-only items marked “can be ignored” internally.
  2. Perform a test upgrade on a snapshot-restored instance to catch the RDS-only items via PrePatchCompatibility.log.

Understanding and resolving pre-upgrade check errors

To show you the pre-upgrade check process and the Error items that block upgrades, we reproduced several Error items on our test environment. In the following sections, we walk you through the actual precheck output and the suggested resolution for each item, so you can interpret and resolve precheck errors in practice.

Issues reported by ‘check table x for upgrade’ command

Runs CHECK TABLE … FOR UPGRADE against each tables. Depending on the scope of impact, the severity varies. The following are examples of both Error and Warning types.

Check item

(Error)

Issues reported by ‘check table x for upgrade’ command

  • db1.t_1 – View ‘db1.t_1’ references invalid table(s) or column(s) or function(s) or definer/invoker of view lack rights to use them
  • db1.t_1 – Corrupt

Description

The View references a table, column, or function that no longer exists, or the definer/invoker lacks the required privileges. The “Corrupt” status indicates this is an Error-level finding that blocks the upgrade.

Remediation

Identify the invalid references and remove or fix them:

  • Drop the invalid View if no longer needed.
  • Or recreate the missing base table so the View becomes valid again.

Check item

(Warning)

Issues reported by ‘check table x for upgrade’ command

  • db2.t_2 – Row size too large (> 8126). Changing some columns to TEXT or BLOB or using ROW_FORMAT=DYNAMIC or ROW_FORMAT=COMPRESSED may help. In current row format, BLOB prefix of 768 bytes is stored inline.

Description

The table uses COMPACT or REDUNDANT row format, where each BLOB/TEXT column stores a 768-byte prefix inline. With many such columns, the total row size exceeds InnoDB’s 8126-byte page limit.

Remediation

Changing some columns to TEXT or BLOB or using ROW_FORMAT=DYNAMIC or ROW_FORMAT=COMPRESSED may help. This is a Warning item and does not block the upgrade, but INSERT or UPDATE operations that exceed the row size limit may fail after the upgrade.

Note: Changing the row format or altering column types triggers a table rebuild. For large tables, consider running during a maintenance window or using an online DDL tool.

Check for deprecated or removed plugin usage

Check item

Check for deprecated or removed plugin usage.

  • <plugin_name> – deprecated/removed plugin detected.

Description

RDS for MySQL does not support installing the plugins that the precheck scans for (authentication_fido, keyring_file, keyring_encrypted_file, keyring_oci), so this item cannot be reproduced. If detected, remove the reported plugin(s) and retry the upgrade.

Remediation

Uninstall the plugin(s) if found.

Checks for errors in column definitions

Check item

Checks for errors in column definitions. Identifies column definitions that may not be supported in future versions of MySQL.

  • db1.t3.id – The column is of type DOUBLE and has the AUTO_INCREMENT flag set, this is no longer supported.
  • db1.t4.id – The column is of type FLOAT and has the AUTO_INCREMENT flag set, this is no longer supported.

Description

Using DOUBLE or FLOAT with AUTO_INCREMENT is no longer allowed in MySQL 8.4. This check and “Use of AUTO_INCREMENT for DOUBLE and FLOAT data types” point to the same affected tables.

Remediation

Change the column type to an integer type (for example: BIGINT).

Check for allowed values in system variables

Check item

Check for allowed values in system variables. The following system variables are using values that are not allowed.

  • ssl_cipher – Error: The system variable ‘ssl_cipher’ is set to ‘DHE-DSS-AES256-SHA’, allowed values include: ECDHE-ECDSA-AES128-GCM-SHA256, ECDHE-ECDSA-AES256-GCM-SHA384, ECDHE-RSA-AES128-GCM-SHA256, ECDHE-RSA-AES256-GCM-SHA384, ECDHE-ECDSA-CHACHA20-POLY1305, ECDHE-RSA-CHACHA20-POLY1305, ECDHE-ECDSA-AES256-CCM, ECDHE-ECDSA-AES128-CCM, DHE-RSA-AES128-GCM-SHA256, DHE-RSA-AES256-GCM-SHA384, DHE-RSA-AES256-CCM, DHE-RSA-AES128-CCM, DHE-RSA-CHACHA20-POLY1305

Description

Checks whether system variables use values that are no longer allowed in MySQL 8.4.

Remediation

Find non-default system variables and change the value(s).

Checks for partitions by key using columns with prefix key indexes

Check item

Checks for partitions by key using columns with prefix key indexes. Indexes on column prefixes are not supported for key partitioning, they are ignored by the partition function and so they are not allowed as of 8.4.0. This check identifies tables with partitions defined this way, they should be fixed before upgrading to 8.4.0. More information: Partitioning limitations

  • db1.t5 – Error: the db1.t5 table uses partition by KEY using the following columns with prefix index: name.

Description

Tables partitioned by key using columns with prefix key indexes are no longer compatible in MySQL 8.4.

Remediation

If the partition key column uses a prefix index (for example: KEY(col(10))), remove the prefix and use the full column, or redesign the partition strategy (for example: switch to RANGE or HASH).

Use of AUTO_INCREMENT for DOUBLE and FLOAT data types

Check item

Use of AUTO_INCREMENT for DOUBLE and FLOAT data types. Starting with MySQL version 8.4.0, the use of AUTO_INCREMENT is deprecated for DOUBLE and FLOAT data types.

  • db1 – Don’t use AUTO_INCREMENT with DOUBLE and FLOAT data types.

Description

This is the RDS-specific check for the same issue as “Checks for errors in column definitions”. Both checks point to the same affected tables.

Remediation

Same as “Checks for errors in column definitions” — change the column type to an integer type.

RDS checked for the use of non-inclusive language in SQL statements

Check item

RDS checked for the use of non-inclusive language in SQL statements. Starting with MySQL version 8.4.0, the use of non-inclusive language in SQL statements isn’t allowed.

  • [ROUTINE_SCHEMA, ROUTINE_NAME]
  • db1,sp1 – Don’t use SQL statements that contain MASTER or SLAVE.

Description

Starting with MySQL 8.4.0, non-inclusive language (for example: MASTER, SLAVE) in SQL statements is no longer allowed.

Remediation

Replace non-inclusive keywords:

  • MASTER → SOURCE
  • SLAVE → REPLICA
  • SHOW MASTER STATUS → SHOW BINARY LOG STATUS
  • SHOW SLAVE STATUS → SHOW REPLICA STATUS

memcached plugin needs to be uninstalled before upgrade

Check item

memcached plugin needs to be uninstalled before upgrade. Starting with MySQL version 8.3.0, the InnoDB memcached plugin is no longer supported.

  • [name]
  • daemon_memcached – Remove the MySQL memcached support option from your DB instance and then retry the upgrade.

Description

The InnoDB memcached plugin is no longer supported starting with MySQL 8.3.0. Remove it before upgrading.

Remediation

Remove the MEMCACHED option from the Option Group associated with the DB instance.

DB instance must have enough free disk space

Check item

DB instance must have enough free disk space. The DB instance must have at least 2 GiB free space for an upgrade to MySQL 8.0.30 and above.

  • Make sure you have more than 2147483648 bytes available for the DB instance.
  • Scale storage so that there is at least 2 GiB free space before retrying the upgrade.

Description

The DB instance must have at least 2 GiB of free disk space for upgrades to MySQL 8.0.30 and above.

Remediation

Scale up the storage so that the instance has more than 2 GiB of free storage space (FreeStorageSpace).

Detect system objects created as tables in sys schema

Check item

Detect system objects created as tables in sys schema.

  • <table_name> – system object created as a table in sys schema.

Description

Detects whether system objects in the sys schema have been created as regular tables. These objects can conflict during the upgrade process.

Remediation

If results are returned:

1. Back up the data from the table.

2. Remove the sys.<table_name>.

Key compatibility changes in MySQL 8.4

The following changes most commonly affect RDS for MySQL upgrades:

mysql_native_password deprecation: MySQL 8.4 defaults to caching_sha2_password. Existing users with mysql_native_password continue to work after the upgrade, but newly created users will use caching_sha2_password. To change the default authentication plugin, modify the authentication_policy parameter in your DB parameter group. If you do not plan to keep using mysql_native_password, consider switching affected users to caching_sha2_password on your MySQL 8.0 instance and validating application connectivity before proceeding with the upgrade.

Applications using older client drivers that do not support caching_sha2_password will fail to connect with the error: Authentication plugin ‘caching_sha2_password’ cannot be loaded. The following minimum driver versions are required:

Query affected users:

restrict_fk_on_non_standard_key: New parameter in MySQL 8.4 (default ON) that blocks CREATE TABLE and ALTER TABLE statements from creating foreign keys on non-unique or partial keys. This does not affect existing foreign keys or the upgrade itself. It only applies to data definition language (DDL) operations after the upgrade. If your application creates or modifies foreign keys at runtime, set this parameter to OFF in your MySQL 8.4 parameter group, or adjust your DDL statements accordingly.

memcached plugin removal: If enabled in your option group, disable it before upgrading (the RDS pre-upgrade validation can also flag this as an Error).

Parameter default value changes in MySQL 8.4

Beyond the compatibility changes above, MySQL 8.4 also changes the default values for several system variables. If you have explicitly set some of these in your MySQL 8.0 parameter group, verify whether your values need to carry over to the MySQL 8.4 parameter group. If you are using the engine defaults, be aware of the new behavior. The following table only includes parameters that are modifiable in the RDS for MySQL 8.4 parameter group.

Parameter 8.0 default 8.4 default
group_replication_consistency EVENTUAL BEFORE_ON_PRIMARY_FAILOVER
group_replication_exit_state_action READ_ONLY OFFLINE_MODE
innodb_adaptive_hash_index ON OFF
innodb_buffer_pool_instances 8 (or 1 if innodb_buffer_pool_size < 1 GB) MAX(1, #vcpu/4)
innodb_change_buffering all none
innodb_io_capacity 200 10000
innodb_io_capacity_max 200 2 × innodb_io_capacity
innodb_numa_interleave OFF ON
innodb_page_cleaners 4 innodb_buffer_pool_instances
innodb_parallel_read_threads 4 MAX(#vcpu/8, 4)
innodb_read_io_threads 4 MAX(#vcpu/2, 4)

You can check which parameters have been explicitly modified in your current parameter group:

For the complete list of changes, see Amazon RDS for MySQL LTS version 8.4 is now generally available.

Go/no-go checklist

Before proceeding to Phase 2, confirm:

Phase 2: Blue/Green Deployments (minimize downtime)

Amazon RDS Blue/Green Deployments lets you upgrade the major engine version, without affecting production. When you’re ready, you promote the staging environment to become the new production database with downtime typically five seconds or lower for single-Region configurations. This makes Blue/Green Deployments a practical choice for major version upgrades with minimal disruption. The following sections walk you through creating Blue/Green Deployments, upgrading the green environment to MySQL 8.4, and performing the switchover.

Prechecks

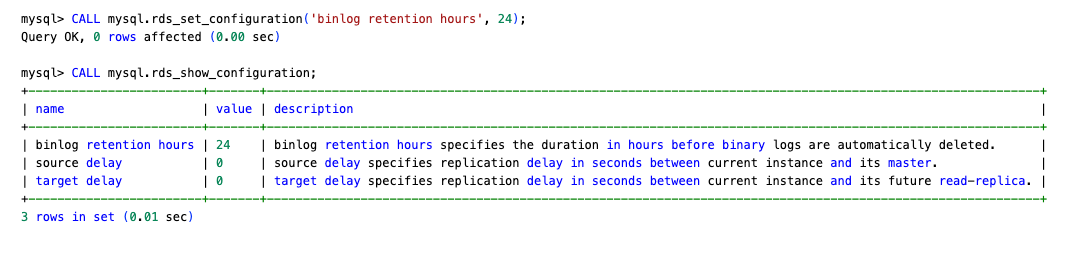
Before creating the deployment, confirm:

RDS console showing binlog retention hours configuration result

Create and upgrade the green environment

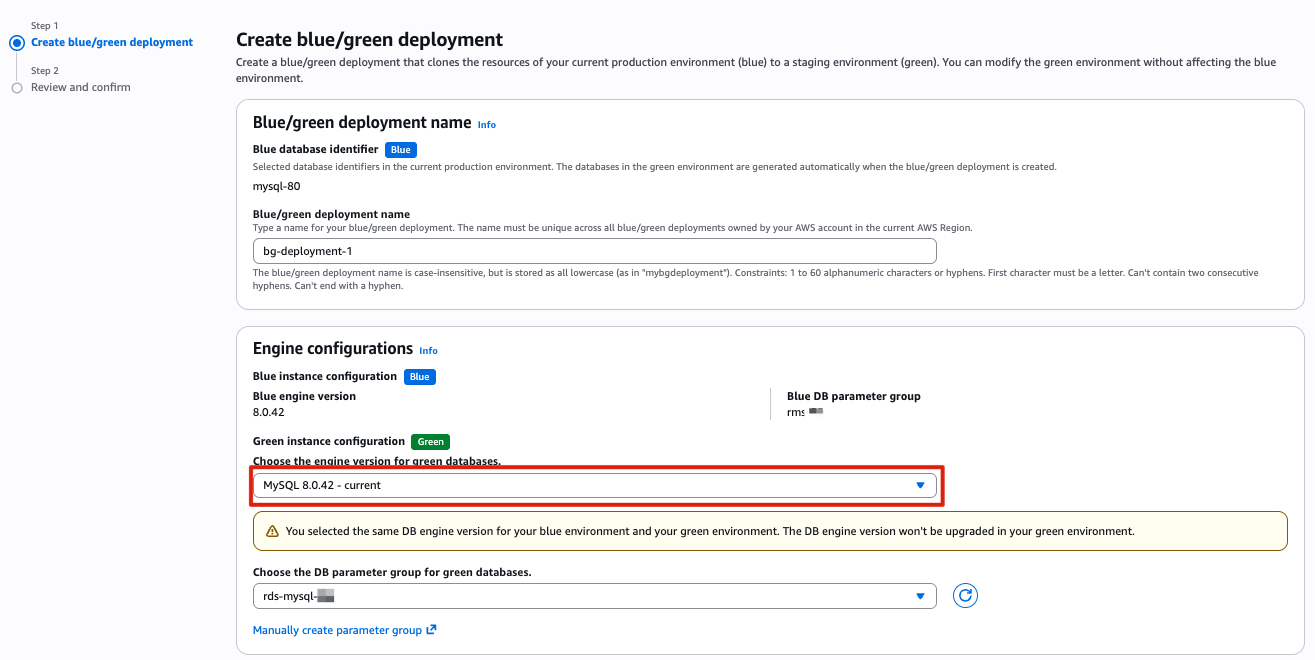
  1. Create the Blue/Green Deployments: Select the same engine version as the source instance initially. This avoids a failed automatic upgrade requiring you to rebuild the entire deployment.

RDS console showing Blue/Green Deployment creation with same engine version selected

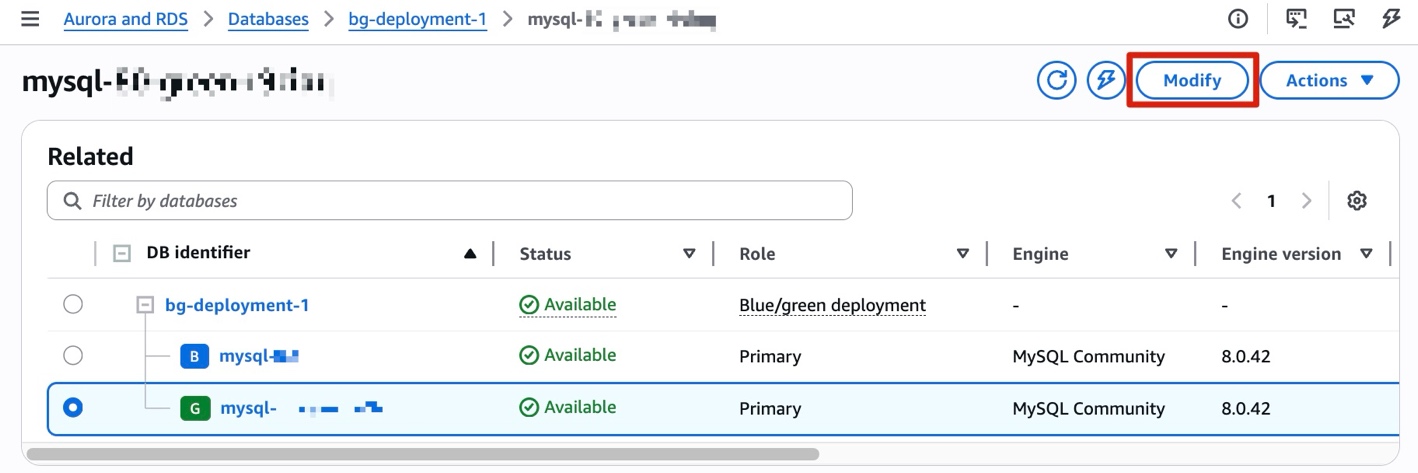
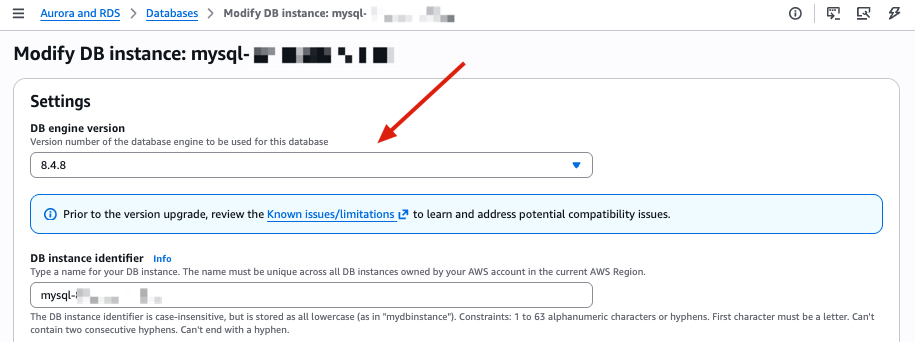
  1. After creation completes, manually upgrade the green instance to MySQL 8.4.x. Select your pre-configured MySQL 8.4 parameter group, or the default parameter group if you’re not customizing any parameters.

RDS console showing the green instance modification to upgrade to MySQL 8.4

RDS console showing MySQL 8.4 parameter group selection during green instance upgrade

  1. If the upgrade fails, check the green instance’s PrePatchCompatibility.log and Recent events for details. Resolve the issues and retry.
  2. (Optional) If you plan to set up a rollback path in Phase 3, verify that binlog retention on the green instance (MySQL 8.4) is set to at least 24 hours before switchover. Otherwise, binlog files might be purged after switchover, making reverse replication impossible.

Switchover

Before switching over:

  • Confirm ReplicaLag on the green instance is near zero.
  • Check for long-running queries on the blue instance (SHOW PROCESSLIST).
  • Verify both environments show Available status.
  • Verify that the application isn’t caching DNS, or if it is then the cache TTL is 5 seconds or less.
  • Complete the rollback setup in Phase 3 first

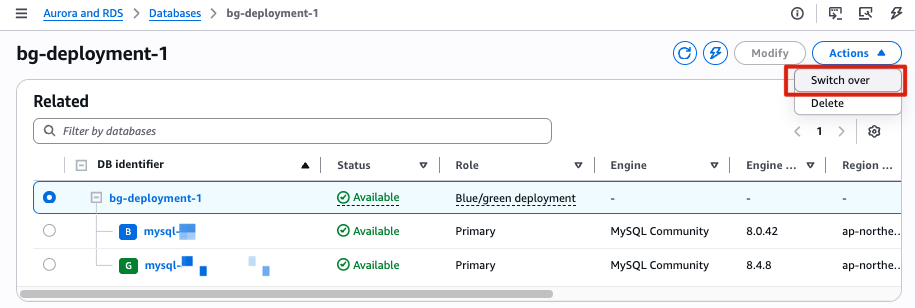
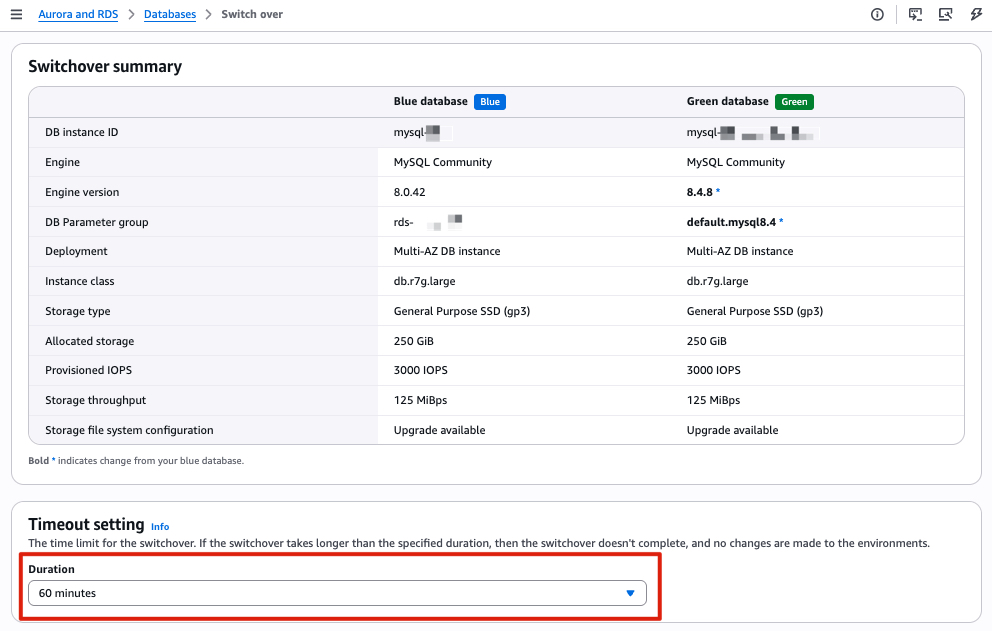
Set the switchover timeout to your acceptable downtime window (maximum 60 minutes). During switchover, existing connections are dropped.

RDS console showing the Blue/Green Deployment switchover configuration with timeout setting

RDS console showing the switchover confirmation dialog

After a successful switchover, RDS renames the old instance with a -old1 suffix and sets it to read-only. The new MySQL 8.4 instance takes the original name and endpoint. RDS automatically disconnects replication at this point. Blue/Green Deployments is a one-time operation. You can delete the Blue/Green Deployments at your convenience; doing so does not delete the old instance. If you do not need a rollback path, the upgrade is complete at this point.

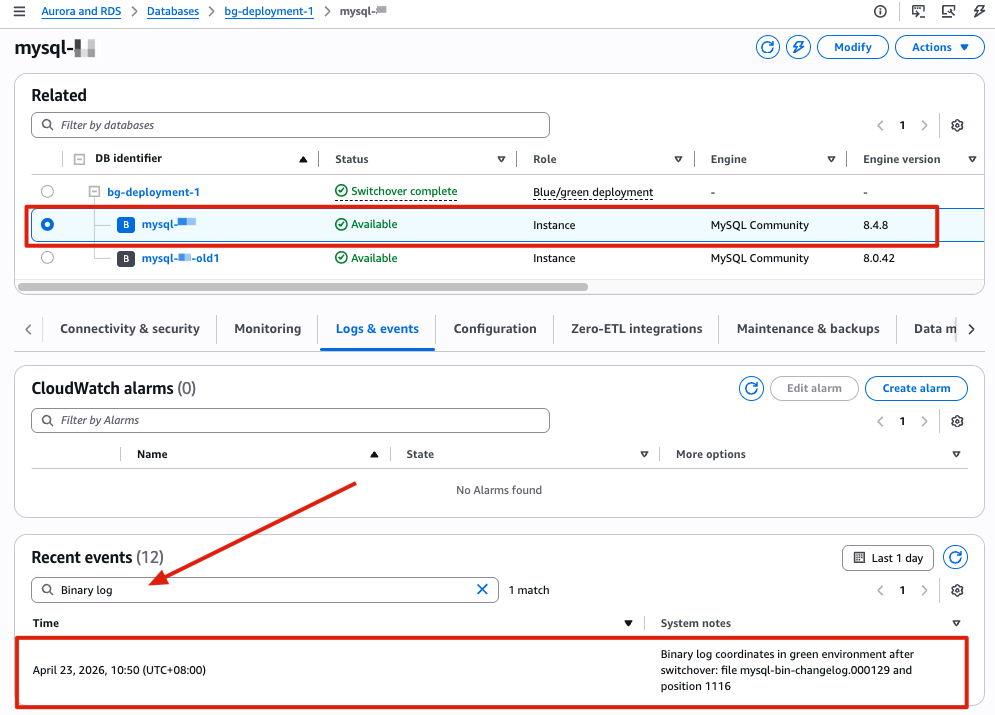
Important: Note the binlog position recorded after switchover completed, you will need it for the rollback setup in Phase 3. Following these steps to find the binlog position after switchover:

  1. Open the Amazon RDS console and select your new MySQL 8.4 instance.
  2. Open the Logs & events tab and search for Binary log. Note the last recorded binlog file name and position. For example, in our test environment, the values are mysql-bin-changelog.000129 and position 1116.

RDS console Logs and events tab showing the binary log file name and position after switchover

Phase 3: Rollback preparation

Set up reverse replication from the new MySQL 8.4 instance to the old MySQL 8.0 instance after switchover, so you have a working rollback path if issues arise post-upgrade. This approach uses change data capture (CDC) to synchronize only incremental changes. The key input is the binlog position recorded in the switchover event (Logs & events → Recent events on the new MySQL 8.4 instance). Use this position to establish reverse replication back to the old 8.0 instance.

The following table provides a brief comparison between Option A (native replication) and Option B (AWS DMS) to help you choose the approach that best fits your environment:

Criteria Native Replication AWS DMS
Setup complexity Lower Higher
Additional cost None DMS instance cost
LOB handling Automatic Requires DMS task configuration
When to use Direct network connectivity available Complex environments or when native replication isn’t feasible

Option A: Native replication (preferred)

Migration between RDS for MySQL instances is a homogeneous data migration. We recommend native replication as the preferred approach, because native database migration tools generally provide better performance and accuracy compared to AWS DMS.

After switchover, you do not need to change the read_only parameter to 0 on the MySQL 8.0 -old1 instance. In replication setups, it can be useful to enable read_only on replica servers to make sure that replicas accept updates only from the source server and not from clients.

  1. Retrieve the binlog position from the new MySQL 8.4 instance (Logs & events → Recent events).
  2. On the MySQL 8.4 instance, create a replication user.
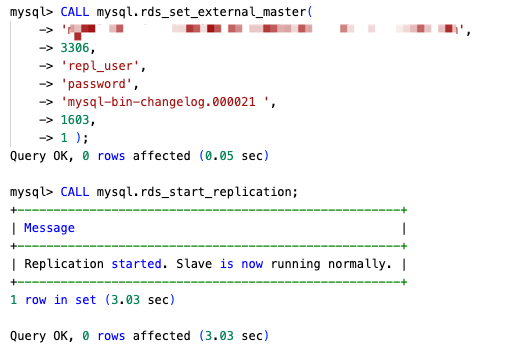
  1. On the MySQL 8.0 -old1 instance, configure replication using the binlog position from step 1:

MySQL console output showing successful replication configuration with rds_set_external_master and rds_start_replication

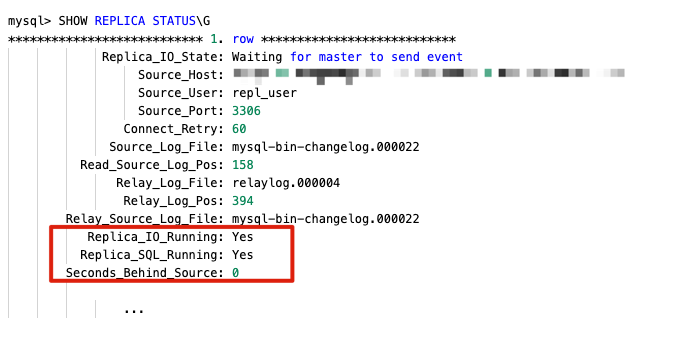
  1. Verify with SHOW REPLICA STATUS\G and confirm the following:
    • Replica_IO_Running: Yes
    • Replica_SQL_Running: Yes
    • Seconds_Behind_Master is decreasing, approaching 0, and is not -1 or NULL

SHOW REPLICA STATUS output confirming Replica_IO_Running and Replica_SQL_Running are both Yes

Option B: AWS DMS

If native replication is not suitable for your environment, you can use AWS DMS as an alternative to set up the rollback path.

Because the MySQL 8.0 -old instance is set to read-only after switchover, change the read_only parameter to 0 in its parameter group before creating the task.

  • Step 1: Create a DMS replication instance
    • Instance class & Allocated storage: based on workload
    • Engine version: use the default
    • Virtual private cloud (VPC): use the same VPC as both the MySQL 8.4 (source) and MySQL 8.0 (target) instances. Note: If the source and target instances are in different VPCs, you need to configure VPC peering or another network connectivity option before creating the replication instance.
  • Step 2: Create DMS endpoints
    • Source endpoint: use the MySQL 8.4 instance endpoint (after switchover)
    • Target endpoint: use the old MySQL 8.0 -old1 instance endpoint
    • Test both endpoint connections from the replication instance before proceeding
  • Step 3: Create a CDC-only DMS task
    • Migration type: CDC only (ongoing replication)
    • CDC start position: enter the binlog position from the switchover event (Logs & events → Recent events on the new MySQL 8.4 instance)
    • Include LOB columns in replication: if your tables contain LOB columns, consider using Limited LOB mode for faster replication. This mode truncates LOB value that exceeds the configured Maximum LOB size, so you need to set it appropriately.
    • Maximum LOB size (KB): query the maximum LOB size in your instance first, then set accordingly:
  • Table mappings: either explicitly include the databases you want to synchronize, or use % to include every database and exclude system databases (mysql, sys, information_schema, performance_schema).
  • Step 4: Monitor the task
    • Once the task status shows Replication ongoing, CDC synchronization is active and the rollback path is ready.

Once you have validated that the new RDS for MySQL 8.4 environment is working as expected, you can stop the DMS replication task and delete the old RDS for MySQL 8.0 instance.

Clean up

After completing the upgrade and confirming your application is running normally on MySQL 8.4, you should remove the resources created during this process to avoid incurring additional charges. Follow these steps in the AWS Management Console or the AWS Command Line Interface (AWS CLI):

  • Deleting Blue/Green Deployments (deleting the deployment does not delete the DB instances).
    1. Open the Amazon RDS console and choose Databases.
    2. Select the Blue/Green Deployment → Choose Actions → ‘Delete’.
  • Snapshot-restored RDS instance used for pre-upgrade checks.
  • The old RDS for MySQL 8.0 -old1 instance (after you confirm rollback is no longer needed). For more AWS CLI options, see Deleting a DB instance.
    1. Open the Amazon RDS console and choose Databases.
    2. Select the instance → Choose ‘Actions’ → ‘Delete’.
  • Amazon EC2 instance used for running prechecks (if applicable). For more AWS CLI options, see Terminate Amazon EC2 instances.
    1. Open the Amazon EC2 console and choose Instances.
    2. Select the EC2 instance used for running prechecks → Choose ‘Instance state’ → ‘Terminate (delete) instance’.
  • AWS DMS replication instance, endpoints, and task (if you used Option B for rollback).
    • Tasks:
      1. Open the AWS DMS console and choose Tasks.
      2. Select the DMS task used for rollback.
      3. If the task is still running, choose ‘Actions’ → ‘Stop’.
      4. After the task has stopped, choose ‘Actions’ → ‘Delete’.
    • Endpoints:
      1. Choose Endpoints.
      2. Select the source and target endpoints → Choose ‘Actions’ → ‘Delete’.
    • Deleting a replication instance:
      1. Choose Provisioned instances.
      2. Select the replication instance → Choose ‘Actions’ → ‘Delete’.

Conclusion

In this post, we walked through a three-phase approach for upgrading Amazon RDS for MySQL 8.0 to 8.4: interpreting pre-upgrade compatibility checks, performing the upgrade with minimal downtime using Amazon RDS Blue/Green Deployments, and setting up a rollback path with reverse replication. These phases give you a tested, reversible upgrade path with minimal downtime, reducing the risk that typically stalls major version upgrades. With MySQL 8.0 standard support ending on July 31, 2026, we encourage you to start planning your upgrade and validating your workloads against MySQL 8.4’s new features and performance improvements. If you need to continue using MySQL 8.0 beyond the standard support end date, see the breakdown of Extended Support costs in Upgrade strategies for Amazon RDS for MySQL 8.0 to 8.4.

To learn more, see Upgrading a MySQL DB instance engine version and Using Amazon RDS Blue/Green Deployments. If you have questions or feedback, leave a comment on this post.


About the authors

Nicky Hsu

Nicky Hsu is a Cloud Support Engineer II at AWS Support and a Subject Matter Expert in RDS for MySQL and Aurora PostgreSQL. With 3 years at AWS and 8 years of experience in the IT industry, he specializes in providing technical support for Amazon RDS for MySQL, RDS for MariaDB, Aurora MySQL, RDS for PostgreSQL, Aurora PostgreSQL, and AWS DMS, helping customers troubleshoot issues and implement tailored solutions.

Planet for the MySQL Community

ProxySQL in Front of AWS RDS & Aurora MySQL — Part 1: Why and Where to Place It

https://reliadb.com/images/og-default.png

At 14:32 on a Tuesday, a writer failover hit an Aurora MySQL cluster in production. Aurora did its job: within about 30 seconds, a reader had been promoted, the cluster endpoint had been updated, and replication was running in reverse. From the database’s perspective, the failover was clean.

From the application’s perspective, it was messy. The reader endpoint kept serving connections — sort of. For roughly 60 seconds, a portion of connections returned ETIMEDOUT, others silently fetched data from a replica that was still several seconds behind the new writer, and the connection pool on the now-promoted writer climbed past 900 as every idle connection in every app tier tried to reconnect simultaneously. No data was lost. The failover was technically successful. But that 60-second window caused real downstream pain: cache misses, stale reads that bypassed business-logic checks, and an alert storm that took another 20 minutes to quiet.

AWS managed MySQL is genuinely excellent at operating a database. It handles patching, replication, storage scaling, and failover without you touching the binaries. What it does not do — and was never designed to do — is solve the proxy layer. That problem is still yours.

This five-part series is about exactly that problem: deploying ProxySQL in front of RDS and Aurora MySQL, from the first architectural decision all the way to operating it in production. Part 1 is conceptual. It covers the why, the where, and the decision framework. No shell commands here — those start in Part 2.

WHAT YOU’LL BUILD: A production-representative ProxySQL topology sitting in front of Aurora MySQL — connection multiplexing, read/write splitting with query-level rules, a ProxySQL Cluster for config HA, and Aurora-native topology discovery. The same lab topology runs unchanged across all five parts so you can follow each step end-to-end.

The Problem with RDS and Aurora Endpoints Alone

Before reaching for any proxy, it’s worth naming the specific problems you’re trying to solve. RDS and Aurora expose several endpoint types — cluster endpoint, reader endpoint, instance endpoints — and they cover a lot of ground. But each has a hard limit that surfaces when your workload grows or your topology changes under pressure.

The Aurora Reader Endpoint and Its Limits

The reader endpoint distributes connections across all reader instances in the cluster via DNS-based round-robin. It works, and for many workloads it’s entirely sufficient. The limits emerge when you need more than "roughly even distribution."

The first limit is routing intelligence: it has none. The reader endpoint routes TCP connections, not SQL. It doesn’t know what query is being sent. You can’t direct long-running analytics queries to a larger reader instance while keeping the smaller one for OLTP reads. Every connection gets identical treatment regardless of what it does next.

The second limit is failover behavior. When Aurora promotes a reader to writer, the cluster endpoint updates within seconds. The reader endpoint takes longer to settle because it reflects the current set of available readers, and clients that already have a DNS answer are holding a cached TTL. Depending on your connection pool’s DNS TTL handling and JVM settings, reads can land on the old writer — now a reader — or on replicas that haven’t fully caught up to the new writer’s binlog position yet. Two consecutive reads in the same application session can hit different replicas with different replication lag, which produces read-your-own-writes violations that are difficult to reproduce and infuriating to debug in production.

RDS Multi-AZ: HA You Can’t Read From

RDS Multi-AZ keeps a synchronous standby in a separate Availability Zone. That standby absorbs the failover cleanly — RDS flips the CNAME, the old primary becomes the new standby, and writes resume. It’s a solid HA story.

The limitation is that the standby is not readable. You pay for a full second instance — same CPU, same memory, same storage class — and get exactly zero read capacity in return. All read traffic still runs through the primary. If your goal is to distribute read load, Multi-AZ does nothing for you.

The failover experience also has a rough edge. The DNS flip typically takes 60–120 seconds to propagate through resolver caches. During that window, apps that don’t aggressively detect dead connections will queue or block against the old endpoint. Connection pools configured with long keepalive intervals or no TCP keepalive will sit on dead sockets without noticing. And there’s no graceful drain — in-flight transactions die the moment the standby promotes. Any retry logic is entirely on the application side.

The Connection Multiplexing Gap

Every client connection to RDS or Aurora is a real MySQL thread on the backend server. There’s no pooling at the managed endpoint layer. A single connection pool with 500 connections means 500 threads on the writer, each holding allocated memory, regardless of whether any of them are actively executing a query at that moment.

This matters at steady state, but it bites hardest during recovery. After a failover, all connections across all your app tiers try to reconnect at roughly the same moment — the thundering herd. Aurora’s max_connections is derived from the instance class: a db.r6g.large supports around 1,000 connections. Three app tiers with 200 connections each, plus monitoring tools and any administrative overhead, and you’re approaching that ceiling before the reconnect storm hits. The instinctive response — upsize the instance — is expensive and doesn’t change the underlying reconnect pattern.

No Query-Level Intelligence at the Endpoint Layer

The RDS and Aurora endpoint layer is connection-aware, not query-aware. Once a TCP connection is established, what travels over it is invisible to AWS. This means you have no mechanism at the managed layer to block a SELECT * without a WHERE clause from a poorly-written ORM, mirror production traffic to a staging replica to validate a schema change under real load, throttle an analytics query that’s crowding out OLTP reads, or enforce per-application connection limits so one service can’t exhaust the pool for everyone else. These are DBA problems. The managed endpoint layer doesn’t solve them, and it’s not going to.

SYMPTOMS YOU’VE PROBABLY SEEN: Thundering herd on the writer immediately after failover as all connection pools reconnect simultaneously. Stale reads surfaced by a sticky-session bug when a load balancer pins a user to a lagging replica. Connection storms during blue-green deploys when both environments briefly hold a full connection pool against the same writer endpoint.

What ProxySQL Gives You (in 90 Seconds)

ProxySQL is a MySQL-protocol proxy. It sits between your application and your MySQL backends, speaking the MySQL client/server protocol on both sides — the application thinks it’s talking to MySQL directly, and the MySQL backends think ProxySQL is just another client. Nothing changes at either end. You don’t modify your driver, your connection string format (beyond hostname and port), or your SQL. The proxy layer is fully transparent to the application.

What changes is what happens in the middle.

The three-layer config model is the first thing to internalize, because it’s unlike every other proxy you’ve probably used. ProxySQL maintains three distinct layers: MEMORY (a staging scratchpad), RUNTIME (the live, actively-used configuration), and DISK (the persisted sqlite3 database). You stage changes in MEMORY, validate them, then explicitly promote to RUNTIME with a LOAD ... TO RUNTIME command. You persist to DISK separately with SAVE ... TO DISK. There’s no config file reload, no signal to send, no service restart. Changes are atomic and deliberate by design.

Hostgroups are ProxySQL’s abstraction over backend servers. You assign each MySQL instance to a hostgroup — writer in HG 10, readers in HG 20 — and ProxySQL handles routing between them. It monitors backend health by polling read_only on standard MySQL replication. For Aurora clusters, Part 2 will show how mysql_aws_aurora_hostgroups tells ProxySQL to query INFORMATION_SCHEMA.REPLICA_HOST_STATUS instead, giving it true Aurora-native topology awareness that survives Aurora-specific failover events.

Query rules map SQL patterns to hostgroups. A rule matching ^SELECT routes reads to HG 20; a rule matching ^SELECT.*FOR UPDATE sends locking reads to HG 10. Rules can be stacked, prioritized, weighted, and scoped by user or schema. Part 3 covers query rules in depth — the point here is that routing happens per statement, not per connection.

Connection multiplexing lets N frontend connections share M backend connections, where M is much smaller than N. ProxySQL tracks per-session state — autocommit status, active transactions, SET variable assignments, temporary tables, advisory locks — to determine when a backend connection is safe to hand to a different frontend client. For workloads with many idle or short-lived connections, this can collapse backend thread counts by an order of magnitude.

Query mirroring clones traffic from the production hostgroup to a secondary hostgroup — a staging replica, a new Aurora cluster version, a read replica under evaluation. Mirrored queries are fire-and-forget: results are discarded, application latency is unaffected, and the calling code never knows the traffic was duplicated. It’s the cleanest way to validate infrastructure changes under real production query patterns without touching the critical path.

Native MySQL protocol means no driver changes and no protocol translation overhead. Applications see ProxySQL as a standard MySQL endpoint; the authentication handshake is transparent. If you’ve used pgBouncer for PostgreSQL connection pooling, ProxySQL multiplexing solves the same connection-count problem at the MySQL protocol layer — but with per-statement query awareness layered on top.

Placement Options on AWS

Where you deploy ProxySQL on AWS is the most consequential architectural decision in this series. Get it wrong and you’ll be managing config drift, single-AZ blast radius, or hidden latency for as long as the deployment lives. There are four viable patterns, each a legitimate choice, and none universally correct.

App-Side Sidecar (Per-EC2 or Per-ECS Task)

In the sidecar pattern, a ProxySQL process runs on every application server or alongside the application container in every ECS task. The app connects to 127.0.0.1:6033 — a loopback address. There’s zero extra network hop between the application and the proxy. For latency-sensitive workloads where even sub-millisecond overhead matters, this is the right answer.

The operational challenge matches the latency advantage: you now have N ProxySQL instances to keep aligned. If your fleet has 40 EC2 instances and you push a query rule change, that change needs to land on all 40 — or you’ll have instances routing traffic differently from each other, in a way that’s hard to reproduce during an incident. Config drift across instances is the primary failure mode of this pattern. It doesn’t surface immediately; it bites you three months later when you discover eight instances are running a config from six weeks ago.

You can manage this cleanly with automation: ProxySQL config delivered via SSM Parameter Store and applied at instance launch, AWS AppConfig for runtime pushes, or Ansible/Chef. Without that automation in place before you adopt this pattern, the pattern will work against you. AZ resilience is inherited from your application tier — if your app runs across three AZs, so do your sidecar ProxySQL instances.

Best for: teams with mature, tested config automation; workloads where sub-millisecond proxy latency matters; single-application environments connecting to a single cluster.

Centralized Fleet Behind NLB

In the centralized pattern, two or more ProxySQL EC2 instances run in an Auto Scaling Group in private subnets, fronted by an AWS Network Load Balancer. Applications point at the NLB DNS name. The NLB handles health checks and distributes incoming TCP connections across the ProxySQL fleet.

The latency addition is real but small: an NLB in the same Availability Zone as the application typically adds under 0.5ms of round-trip time. Cross-AZ adds 1–2ms. For the vast majority of database workloads — even high-frequency OLTP — this is noise that won’t appear in your P99 latency graphs.

The operational win is significant: one config surface for every application connected to the database layer. Push a query rule change to two ProxySQL instances and every application sees it within seconds, with no per-host coordination. Rolling upgrades work cleanly via ASG instance refresh — drain one node, upgrade, re-add, repeat. The risk is blast radius: a misconfiguration that reaches RUNTIME on a centralized fleet affects all applications simultaneously. Mitigate this with a promotion discipline: apply to MEMORY on one node, smoke-test, then promote across the fleet. Part 5 covers a practical runbook for this.

Best for: environments with multiple applications sharing the same cluster; ops teams who want a single "database layer" to reason about; teams without mature per-host config automation.

Kubernetes Sidecar (EKS)

On EKS, the sidecar pattern maps naturally to Kubernetes: ProxySQL runs as a container in the same pod as the application container, sharing the pod’s network namespace. The app connects to localhost:6033 — same zero-hop benefit as the EC2 sidecar.

Configuration arrives via a ConfigMap or Secret, with ProxySQL reloading on change via an init container, a lifecycle hook, or a purpose-built controller. The proxy lifecycle is tied to the pod: when a pod scales up, a new ProxySQL instance comes with it; when the pod terminates, so does the proxy. No orphaned state to clean up.

One metric demands attention from the start: the connection count arriving at Aurora. At 500 application pods with a ProxySQL sidecar each holding ~10 backend connections after multiplexing, you can land 5,000 MySQL threads on the writer. Multiplexing helps inside each sidecar — it doesn’t help across them. Aurora’s max_connections sees those 5,000 threads regardless of where they originate. Size your multiplexing configuration and your Aurora instance class together, and monitor max_connections headroom continuously.

Best for: EKS-native shops already running the sidecar pattern; environments where the application deployment model should own the proxy lifecycle.

Dedicated ProxySQL Cluster Pair

Two ProxySQL instances configured as a ProxySQL Cluster, placed in separate Availability Zones, fronted by an NLB or round-robin DNS. This is what this series builds in the lab, and it’s the pattern we recommend for most production MySQL deployments.

The defining capability is automatic config synchronization. Configure the two nodes as a cluster via the proxysql_servers table, and any runtime config change applied to either node — new query rules, backend changes, user additions, global variable updates — propagates to the peer automatically, typically within a few hundred milliseconds. You apply a change once, and both nodes converge. No per-host coordination, no push scripts, no drift.

The upgrade story is clean: remove one node from NLB rotation, upgrade its ProxySQL binary, reconnect, then do the same for the second node. You never take the proxy layer entirely offline. AZ resilience comes from placing the two nodes in different Availability Zones — if one AZ becomes unavailable, the NLB routes all traffic to the surviving node.

This is the topology the lab runs throughout this series. Part 4 covers the complete HA and failover story for this pattern, including NLB health check configuration and Aurora-specific event handling.

Deployment Model Latency Add Config Sync Upgrade Path AZ Resilience Best For
App-side sidecar 0 ms Per-host automation required Rolling per instance Inherits app tier spread Low-latency, single app, mature config automation
Centralized + NLB < 0.5 ms intra-AZ Centralized (one config surface) ASG instance refresh Multi-AZ ASG + NLB Multi-app environments, ops-centric teams
K8s sidecar (EKS) 0 ms ConfigMap / Secret push Rolling pod restart Inherits pod spread EKS-native teams, pod-lifecycle ownership
Dedicated cluster pair < 0.5 ms intra-AZ Auto-sync via proxysql_servers Rolling node-by-node, zero downtime 2 nodes in different AZs Production default; this series’ model

ProxySQL Cluster: Why You Always Run Two Nodes

A single ProxySQL node is a single point of failure in two distinct ways, and both matter.

The first is the obvious one: one node means one traffic failure point. If that instance goes down — kernel panic, OOM kill, network partition, or emergency maintenance — your application loses the proxy layer entirely. You could re-point apps directly at Aurora as a fallback, but that immediately eliminates the routing rules and multiplexing configuration your application has been relying on.

The second failure mode is less obvious: a single ProxySQL node is also a single point of config change failure. If you apply a config change that breaks routing and need to roll it back immediately, you need the node to be responsive. If the problem is the node itself, you have nothing to fall back to.

Two nodes in a ProxySQL Cluster solve both problems. The proxysql_servers table on each node lists the other as a peer. When you apply a config change — any LOAD ... TO RUNTIME paired with SAVE ... TO DISK — ProxySQL propagates that change to all configured peers automatically. What syncs between peers: mysql_servers, mysql_users, mysql_query_rules, and global_variables. Each node maintains its own disk state; cluster sync operates at the runtime layer only. When a new node joins, it auto-bootstraps from existing peers — given a populated proxysql_servers table and matching cluster credentials, the new node fetches the latest runtime config from the peer with the highest epoch on startup. The disk file is local; the cluster state is recoverable.

In the lab for this series, proxysql-1 at 192.168.105.7 and proxysql-2 at 192.168.105.8 are configured as a cluster and propagate changes at approximately 200ms under normal conditions. Smoke test 04-cluster-sync.sh validates this by applying a config change to proxysql-1 and verifying it arrives on proxysql-2 before timing out. Part 4 adds the NLB health-check configuration and Aurora-specific failover hooks that complete this foundation.

Alternatives: When Not to Use ProxySQL

ProxySQL adds a component to your infrastructure that requires operational attention — upgrades, monitoring, understanding failure modes, training the team. Before committing to it, it’s worth being honest about whether you actually need what it provides. Several alternatives are simpler, and the right call for many RDS/Aurora environments is not ProxySQL.

The Aurora Reader Endpoint Alone

If your read workload is uniform — all reads have roughly the same profile, target the same tables, and don’t require per-query routing — the Aurora reader endpoint is likely sufficient. It distributes connections across readers, integrates with Aurora’s native topology discovery, and costs nothing to operate beyond the reader instances themselves. The ~30–60s failover window is acceptable for most applications if the connection pool has sensible retry logic and a short TCP keepalive.

If the reason you’re looking at ProxySQL is that the reader endpoint does round-robin and you want "smarter" distribution, stop and ask whether the routing problem is real. If your readers are the same instance class and the load is uniform, round-robin is close to optimal. Adding ProxySQL for that case alone is operational overhead solving a problem that doesn’t exist.

HAProxy or NLB Alone

HAProxy is battle-tested, handles high connection rates efficiently, and is simpler to operate than ProxySQL. For MySQL, it works at Layer 4: it routes TCP connections, not SQL queries. You can configure health checks against the MySQL port and distribute connections across backend pools, but routing decisions are based on the connection, not the query traveling over it.

If your only need is to spread connections across multiple read replicas with no SQL-layer intelligence, HAProxy or an NLB with IP target groups is a reasonable choice. You give up multiplexing, query rules, and the query digest, but if you don’t need those features, you also avoid the complexity of maintaining them. This is a legitimate trade-off, not a compromise.

RDS Proxy

RDS Proxy is AWS’s managed connection pooler for RDS and Aurora. It handles pooling at the managed layer, integrates with IAM authentication and AWS Secrets Manager for credential rotation, and requires no infrastructure to provision or maintain. For teams that want connection pooling without running their own proxy fleet, it’s worth evaluating seriously.

RDS Proxy added read/write splitting via session-aware routing in 2024, so the basic split is solved. The gap relative to ProxySQL sits in everything beyond that. As of mid-2026, RDS Proxy does not support user-defined query routing rules — you can’t write a rule that sends a specific query pattern to a specific instance. It doesn’t support query mirroring. It doesn’t support query rewriting. The per-statement observability that ProxySQL exposes via stats_mysql_query_digest has no equivalent. And the pricing model — charged per vCPU of the underlying database instance — becomes meaningful at scale.

Feature RDS Proxy ProxySQL
Query routing rules No Yes — regex/digest, per-user, per-schema
Connection multiplexing Yes (managed, opaque) Yes (configurable, observable)
Query mirroring No Yes
Per-statement query digest No Yes (stats_mysql_query_digest)
IAM authentication Yes (native) No (requires workaround)
Operational overhead Low — fully managed Medium — self-managed fleet
Cost model Per vCPU of DB instance EC2 instance + NLB (~$16–20/mo)

Connector-Side Load Balancing

MySQL Connector/J’s replication protocol, the AWS JDBC Driver’s reader/writer splitting, and similar connector-side solutions route queries at the application layer. The driver inspects whether the current context is read-only and routes accordingly. This works — and it works without any proxy infrastructure.

The trade-off is that routing policy lives in application code. If you have five services connecting to the same Aurora cluster and you want to change which queries go to readers, you need to update five codebases and deploy five services. There’s no central audit trail, no place to add a rule that captures all traffic regardless of which service is sending it, and no way for the database team to adjust routing without going through a development cycle. For stable, simple routing that genuinely never changes, this is fine. For anything more dynamic, it’s the wrong layer to own the policy.

The honest summary: if your workload is simple and stable, RDS Proxy or connector-side routing covers the common case with significantly less operational overhead than ProxySQL. ProxySQL is the right tool when you need SQL-layer control that neither of those options provides — and when you’re willing to own the operational cost that comes with it.

Running RDS or Aurora MySQL and feeling the limits?

ProxySQL setup and tuning is one of the most impactful changes a DBA can make for a scaling MySQL environment. If you want expert guidance on placement, query routing, or failover design before committing to an architecture, book a free assessment call.

Book Free Assessment →

The Lab Topology You’ll See Across This Series

TESTED ON LIVE VMs: All configurations and outputs across this series come from a Lima VM lab running on macOS — MySQL 8.0.41 managed by dbdeployer (master + 2 replicas), ProxySQL 2.7.3 (two-node cluster), end-to-end smoke-tested before publication. Four smoke tests cover read/write split, replica shunning, multiplexing, and cluster config sync.

Every part of this series builds on the same four-VM lab. Understanding the topology now means you won’t need to re-orient each time a new part adds configuration on top of it.

                    ┌──────────────────┐
                    │    client-vm     │
                    │  192.168.105.9   │
                    │ sysbench / mysql │
                    └────────┬─────────┘
                             │  MySQL protocol :6033
               ┌─────────────┴─────────────┐
               │                           │
  ┌────────────▼──────────┐   ┌────────────▼──────────┐
  │      proxysql-1       │◄──►│      proxysql-2       │
  │   192.168.105.7       │   │   192.168.105.8       │
  │   ProxySQL 2.7.3      │   │   ProxySQL 2.7.3      │
  │   HG 10: writer       │   │   HG 10: writer       │
  │   HG 20: readers      │   │   HG 20: readers      │
  │   admin :6032         │   │   admin :6032         │
  └────────────┬──────────┘   └────────────┬──────────┘
               │    ProxySQL Cluster sync   │
               │         (~200 ms)          │
               └─────────────┬─────────────┘
                             │  MySQL protocol
                    ┌────────▼─────────┐
                    │  mysql-backends  │
                    │  192.168.105.6   │
                    ├──────────────────┤
                    │ master   :25001  │  ← HG 10 (writer)
                    │ replica1 :25002  │  ← HG 20 (reader)
                    │ replica2 :25003  │  ← HG 20 (reader)
                    └──────────────────┘
VM Name IP Role Services
mysql-backends 192.168.105.6 MySQL master + 2 replicas mysqld ×3 (ports 25001 / 25002 / 25003)
proxysql-1 192.168.105.7 ProxySQL 2.7.3 (primary) proxysql :6032 (admin) :6033 (app)
proxysql-2 192.168.105.8 ProxySQL 2.7.3 (cluster peer) proxysql :6032 (admin) :6033 (app)
client-vm 192.168.105.9 Client / load generator mysql-client, sysbench

PRODUCTION SUBSTITUTION: In the lab, all three MySQL backends run on a single VM managed by dbdeployer — three mysqld processes on different ports on the same host. In production, you’d replace those three endpoints with your Aurora cluster’s individual instance endpoints (not the cluster endpoint or reader endpoint), or your RDS writer endpoint plus read replica instance endpoints. ProxySQL 2.7.3 is binary-compatible with Aurora MySQL 2, which tracks the 8.0.x lineage. Part 2 makes this substitution concrete: we connect to a real Aurora cluster and configure mysql_aws_aurora_hostgroups for Aurora-native topology discovery.

Should You Put ProxySQL in Front of Your RDS/Aurora?

Before spending time on the rest of this series, work through these six questions honestly. They’re designed to help you make the right call, not to steer you toward ProxySQL.

  • Do you need per-query routing rules — sending analytics queries to a dedicated replica, blocking specific patterns from reaching the writer, routing by schema or user context? ProxySQL is the only option in the RDS/Aurora ecosystem that gives you this at the proxy layer, independent of application code.
  • Do you need to mirror production traffic to a staging or canary endpoint without modifying application code? ProxySQL query mirroring is the cleanest path. No alternative in this space provides it.
  • Do you need to throttle, queue, or reject specific query patterns at the infrastructure layer rather than the application layer? ProxySQL query rules with max_connections_per_user, error injection, or active/passive rule switching handle this without a code deploy or application-team involvement.
  • Are you hitting Aurora’s max_connections ceiling on the writer and the instinct to upsize the instance isn’t solving the pattern — either because cost is prohibitive or because connection count scales with pod/instance count? ProxySQL multiplexing is the right lever. It collapses hundreds of idle application connections into a fraction of that number on the backend, without changing any application code.
  • Is your only requirement to spread reads across the Aurora reader endpoint, with no routing rules, no per-query control, and no multiplexing tuning? The reader endpoint handles this natively. Adding ProxySQL for this case alone is overhead in search of a problem.
  • Is your only requirement basic read/write split with no custom routing? Try RDS Proxy or a connector-side driver first. They provide this capability with less operational overhead than a self-managed ProxySQL deployment, and they’re easier to hand to a team that hasn’t run ProxySQL before.

If you answered yes to any of the first four, ProxySQL is worth the investment. If your situation fits only the last two, the simpler option is probably the right one. ProxySQL adds a real operational component — a binary to upgrade, a config layer to understand, failure modes to train for. That overhead pays for itself when the workload demands what ProxySQL provides. It doesn’t pay for itself when you just need round-robin reads.

What’s Next: Wiring ProxySQL to Aurora MySQL

In Part 2, we move from architecture to configuration. We’ll connect ProxySQL to a real Aurora MySQL cluster using mysql_aws_aurora_hostgroups — the Aurora-native table that directs ProxySQL to query INFORMATION_SCHEMA.REPLICA_HOST_STATUS for topology discovery, rather than relying on the read_only polling used for standard MySQL replication. With this configuration, ProxySQL auto-discovers the writer and all reader instances, adapts when Aurora promotes a reader during a failover event, and routes traffic correctly through the cluster-level changes that would trip up a replication hostgroup configured for vanilla MySQL. The lab and production configurations live side by side throughout so you can follow both paths.

M

Mario — ReliaDB

ReliaDB is a specialist DBA team for PostgreSQL and MySQL performance, high availability, and cloud database optimization. More about ReliaDB →

Planet for the MySQL Community

ProxySQL in Front of AWS RDS & Aurora MySQL — Part 2: Wiring ProxySQL to Aurora MySQL

https://reliadb.com/images/og-default.png

Two errors in 1,485 queries. Both within a 0.1-second window. Then clean traffic again — and the topology had silently changed underneath. That’s the result we recorded running a live failover against a real Aurora MySQL cluster with ProxySQL in front of it. The baseline without ProxySQL, using the Aurora reader endpoint alone: roughly 60 seconds of mixed timeouts, stale reads, and connection pool churn.

Part 1 was architecture — where to place ProxySQL, why you’d bother, how the dedicated cluster pair pattern works. Part 2 is the first set of commands. Everything from Part 1 stays the same: the two-node ProxySQL Cluster on Lima VMs, ProxySQL 2.7.3, the same lab infrastructure. What changes is the backends. We swap the three-node MySQL sandbox for a real Aurora MySQL 3.x cluster, and we configure mysql_aws_aurora_hostgroups — the table that replaces mysql_replication_hostgroups for Aurora-native topology discovery.

Why mysql_aws_aurora_hostgroups, Not mysql_replication_hostgroups

Standard replication hostgroups poll read_only to determine which backend is the writer. Aurora readers do have read_only=ON, so you might expect that mechanism to just work. It mostly does — until it doesn’t, and the ways it fails are specific to Aurora’s promotion model.

The first failure mode is a race condition during failover. When Aurora promotes a reader to writer, there’s a brief window where the promoted instance has read_only=OFF (it’s the new writer) but the old writer’s read_only=ON update hasn’t fully propagated yet. If ProxySQL polls in that window, it can see two read_only=OFF instances simultaneously and flip both into the writer hostgroup — or flip and immediately flip back when the old writer’s state catches up. This "flapping" is a documented race condition that mysql_aws_aurora_hostgroups avoids by reading SESSION_ID rather than read_only. We didn’t trigger this race in the lab, but avoiding it is precisely why mysql_aws_aurora_hostgroups exists in the first place — the table was added to ProxySQL specifically because read_only polling can’t be made reliable on Aurora’s failover model.

The second failure mode is replica lag visibility. Aurora tracks replica lag in INFORMATION_SCHEMA.REPLICA_HOST_STATUS as replica_lag_in_milliseconds. Standard replication hostgroups read lag from SHOW SLAVE STATUS (or SHOW REPLICA STATUS on 8.0+), which on Aurora returns data that doesn’t reflect Aurora’s actual internal replication lag. mysql_aws_aurora_hostgroups reads directly from REPLICA_HOST_STATUS, so lag values are accurate and can drive the max_lag_ms threshold that excludes lagging replicas from the reader hostgroup.

The third failure mode is custom endpoint handling. Aurora custom endpoints — commonly used for analytics replicas — can appear with is_current=0 in REPLICA_HOST_STATUS when they’re not receiving writes or are otherwise isolated from the replication stream. mysql_replication_hostgroups has no mechanism to filter on that field and will route reads to those instances regardless. mysql_aws_aurora_hostgroups accounts for this during discovery.

The mechanism that solves all three is the same: mysql_aws_aurora_hostgroups queries REPLICA_HOST_STATUS directly, identifies the writer by SESSION_ID=MASTER_SESSION_ID, and populates writer and reader hostgroups from that ground truth — not from read_only. There’s no read_only poll, no race window, and no dependency on MySQL replication status tables that Aurora doesn’t maintain in the standard way.

Key columns you’ll configure in the next section:

  • domain_name — a suffix that all backends in this cluster share. Must start with a dot. ProxySQL enforces this with a CHECK constraint; without the leading dot the INSERT fails.
  • writer_hostgroup / reader_hostgroup — which HG numbers receive the writer and readers after each poll cycle.
  • check_interval_ms — how often ProxySQL polls REPLICA_HOST_STATUS on each backend.
  • writer_is_also_reader — whether the writer instance also appears in the reader hostgroup. Accepts 0 or 1 only in ProxySQL 2.7.3 — more on this below.
  • max_lag_ms — replicas lagging beyond this threshold are excluded from the reader hostgroup until lag recovers.

The Aurora Cluster We Built

Smallest viable lab cluster: one writer, one reader, db.t4g.medium instances, Aurora MySQL 3.12.0 (MySQL 8.0.44 wire protocol), us-east-1. The cluster ran in a default VPC with --publicly-accessible set on each instance so the Lima VM host could reach Aurora directly over the host machine’s public IP. The security group was locked to that single /32. In production, Aurora lives inside a VPC with no public access — this configuration exists only so the Lima VMs could connect without a VPN or bastion.

Lab provenance: Tested live on Aurora MySQL 3.12.0 / MySQL 8.0.44 in us-east-1 on 2026-05-08. Cluster destroyed post-capture. Estimated cost: $0.15.

Two CLI commands provision the cluster, followed by one per instance:

# -- create-db-cluster
# Note: --publicly-accessible is an instance-level flag for aurora-mysql,
# not a cluster-level flag. Passing it here returns InvalidParameterCombination.
aws rds create-db-cluster \
  --db-cluster-identifier proxysql-aurora-EXAMPLE \
  --engine aurora-mysql \
  --engine-version 8.0.mysql_aurora.3.12.0 \
  --master-username admin \
  --master-user-password "<password>" \
  --db-subnet-group-name <subnet-group> \
  --vpc-security-group-ids <sg-id>

# -- create writer instance (--publicly-accessible goes here, not on create-db-cluster)
aws rds create-db-instance \
  --db-instance-identifier proxysql-aurora-EXAMPLE-writer \
  --db-cluster-identifier proxysql-aurora-EXAMPLE \
  --db-instance-class db.t4g.medium \
  --engine aurora-mysql \
  --publicly-accessible

# -- create reader instance
aws rds create-db-instance \
  --db-instance-identifier proxysql-aurora-EXAMPLE-reader \
  --db-cluster-identifier proxysql-aurora-EXAMPLE \
  --db-instance-class db.t4g.medium \
  --engine aurora-mysql \
  --publicly-accessible

Once both instances are available, the topology ProxySQL will discover looks like this:

             ┌──────────────────────────────────────┐
             │    proxysql-1 / proxysql-2           │
             │    ProxySQL 2.7.3 Cluster            │
             │    HG 100: writer                    │
             │    HG 101: reader                    │
             └────────────────┬─────────────────────┘
                              │
         domain_name match: .EXAMPLE-SUFFIX.us-east-1.rds.amazonaws.com
         ProxySQL polls REPLICA_HOST_STATUS every check_interval_ms
                              │
          ┌───────────────────▼──────────────────────────────────────┐
          │            Aurora MySQL 3.12.0 Cluster                   │
          │  proxysql-aurora-EXAMPLE.cluster-EXAMPLE-SUFFIX...       │
          ├─────────────────────────┬────────────────────────────────┤
          │ WRITER → HG 100         │ READER → HG 101                │
          │ …-writer.EXAMPLE-SUFFIX │ …-reader.EXAMPLE-SUFFIX        │
          │ SESSION_ID =            │ lag_ms = 0                     │
          │   MASTER_SESSION_ID     │                                │
          └─────────────────────────┴────────────────────────────────┘

ProxySQL Configuration: The Actual Table Inserts

Three tables to configure, in order: mysql_aws_aurora_hostgroups, mysql_servers, mysql_users. Each needs a LOAD ... TO RUNTIME and SAVE ... TO DISK after its changes. That’s the complete wiring.

Step 1 — mysql_aws_aurora_hostgroups

-- mysql_aws_aurora_hostgroups: one row tells ProxySQL how to discover this Aurora cluster
INSERT INTO mysql_aws_aurora_hostgroups (
  writer_hostgroup, reader_hostgroup, active,
  aurora_port, domain_name,
  max_lag_ms, check_interval_ms, check_timeout_ms,
  writer_is_also_reader, new_reader_weight,
  comment
) VALUES (
  100, 101, 1,
  3306, '.EXAMPLE-SUFFIX.us-east-1.rds.amazonaws.com',
  600000, 2000, 800,
  0, 1,
  'part2 Aurora cluster'
);

Walking each column:

  • writer_hostgroup=100, reader_hostgroup=101 — HG numbers for this Aurora cluster. These must not overlap with the Lima MySQL HGs (10/20) already active in this ProxySQL instance.
  • domain_name='.EXAMPLE-SUFFIX.us-east-1.rds.amazonaws.com' — the leading dot is not optional. ProxySQL matches this suffix against instance hostnames returned by REPLICA_HOST_STATUS to scope discovery to this cluster only. Omit the dot and the INSERT fails with a CHECK constraint violation.
  • check_interval_ms=2000 — ProxySQL polls REPLICA_HOST_STATUS on each backend every 2 seconds. The floor on detection latency is Aurora’s internal promotion time (typically 6–30 seconds depending on instance class and cross-AZ conditions); check_interval_ms adds at most one additional polling cycle on top of that floor. Part 5 covers sizing this for production.
  • check_timeout_ms=800 — a poll that takes longer than 800ms is treated as a connection failure. Must be less than check_interval_ms.
  • writer_is_also_reader=0 — writes route to HG 100 only; the writer instance does not appear in HG 101 for reads. In ProxySQL 2.7.3, the only valid values are 0 and 1. Some older ProxySQL documentation references 2 as a valid setting, but the actual CHECK constraint in 2.7.3 rejects it with a constraint error. We confirmed this in the lab.
  • max_lag_ms=600000 — 10 minutes; effectively no lag filtering for this lab. Part 5 covers production tuning.

Step 2 — mysql_servers: The Seed Row

-- mysql_servers: insert the cluster writer endpoint as a discovery seed
-- ProxySQL bootstraps from this single row and auto-discovers all instances
INSERT INTO mysql_servers (hostgroup_id, hostname, port, comment)
VALUES (
  100,
  'proxysql-aurora-EXAMPLE.cluster-EXAMPLE-SUFFIX.us-east-1.rds.amazonaws.com',
  3306,
  'Aurora cluster writer endpoint (seed for discovery)'
);

One row. The cluster endpoint — not an instance endpoint — in HG 100. Once the mysql_aws_aurora_hostgroups row is active and loaded to RUNTIME, ProxySQL polls this seed’s REPLICA_HOST_STATUS and auto-populates the actual writer and reader instance endpoints. You don’t enumerate instances manually. More on what happens next in Section 5.

Step 3 — mysql_users and mysql_query_rules

-- mysql_users: point the app user at HG 100 (writer) by default
-- If the user already exists from a previous lab step, use UPDATE instead of INSERT
-- to avoid a UNIQUE constraint error on (username, frontend)
UPDATE mysql_users SET default_hostgroup=100 WHERE username='app';

-- mysql_query_rules: lower rule_id = higher priority; order matters
-- rule_id 10 must come before 11, or SELECT FOR UPDATE would match ^SELECT first
INSERT INTO mysql_query_rules (rule_id, active, match_pattern, destination_hostgroup, comment)
VALUES
  (10, 1, '^SELECT.*FOR UPDATE$', 100, 'SELECT FOR UPDATE → Aurora writer HG 100'),
  (11, 1, '^SELECT',              101, 'all SELECTs → Aurora reader HG 101');

Step 4 — LOAD TO RUNTIME and SAVE TO DISK

-- Promote all four config layers to runtime, then persist
LOAD MYSQL SERVERS TO RUNTIME;     SAVE MYSQL SERVERS TO DISK;
LOAD MYSQL USERS TO RUNTIME;       SAVE MYSQL USERS TO DISK;
LOAD MYSQL QUERY RULES TO RUNTIME; SAVE MYSQL QUERY RULES TO DISK;
LOAD MYSQL VARIABLES TO RUNTIME;   SAVE MYSQL VARIABLES TO DISK;

Run these on either ProxySQL node. The ProxySQL Cluster syncs runtime state to the peer within approximately 200ms — you apply once, both nodes converge.

After LOAD MYSQL SERVERS TO RUNTIME, the monitor thread begins polling immediately. No restart needed. Give it a few seconds, then check runtime_mysql_servers.

Auto-Discovery in Action

We inserted one mysql_servers row. About 2 seconds after LOAD TO RUNTIME, ProxySQL had finished its first poll cycle and discovered the writer and reader. By the time we captured the snapshot below — about 60 seconds in — the picture had stabilized:

-- runtime_mysql_servers on proxysql-1 (~60s after LOAD TO RUNTIME)
hostgroup_id  hostname                                                           port  status  comment
100           proxysql-aurora-EXAMPLE-reader.EXAMPLE-SUFFIX.us-east-1...        3306  ONLINE  (auto-discovered — actual writer)
100           proxysql-aurora-EXAMPLE.cluster-EXAMPLE-SUFFIX.us-east-1...       3306  ONLINE  Aurora cluster writer endpoint (seed for discovery)
101           proxysql-aurora-EXAMPLE-writer.EXAMPLE-SUFFIX.us-east-1...        3306  ONLINE  (auto-discovered — actual reader)

ProxySQL adds, it doesn’t replace. The cluster endpoint we inserted as a seed stays in HG 100 alongside the auto-discovered writer instance endpoint. In production you’d typically remove the seed once discovery is verified, since the cluster endpoint resolves to the current writer’s instance endpoint anyway and the duplicate entry serves no useful purpose. For this lab we left it in place.

To watch the polling live, query the Aurora monitor log — which lives in the monitor schema, not in main or stats:

-- monitor.mysql_server_aws_aurora_log: 3-row excerpt, DESC by time
-- Correct schema is monitor — not main.mysql_server_aurora_log (that table does not exist in 2.7.3)
SELECT check_utc, hostname, is_writer_per_replica_host_status AS writer_detected, lag_ms
FROM monitor.mysql_server_aws_aurora_log
ORDER BY check_utc DESC
LIMIT 3;
check_utc               hostname (polled)                                         writer_detected                  lag_ms
2026-05-08 10:52:40     proxysql-aurora-EXAMPLE-writer.EXAMPLE-SUFFIX...          proxysql-aurora-EXAMPLE-reader       0
2026-05-08 10:52:38     proxysql-aurora-EXAMPLE-reader.EXAMPLE-SUFFIX...          proxysql-aurora-EXAMPLE-reader       0
2026-05-08 10:52:37     proxysql-aurora-EXAMPLE-reader.EXAMPLE-SUFFIX...          proxysql-aurora-EXAMPLE-reader       0

Every ~2 seconds, ProxySQL polls each backend it knows about. From each backend, it queries INFORMATION_SCHEMA.REPLICA_HOST_STATUS. The writer_detected column shows the instance whose SESSION_ID=MASTER_SESSION_ID — the current writer, as Aurora itself reports it. Notice the row at 10:52:40: ProxySQL polled the instance named "writer", but REPLICA_HOST_STATUS said the actual writer was the instance named "reader". Why?

NAMES DON’T MATCH TOPOLOGY — AND THAT’S FINE: During lab setup, a rename operation with apply-immediately triggered an implicit Aurora failover. The instance we had named "writer" became a reader, and the instance named "reader" became the writer. ProxySQL ignored both instance names entirely. It queried INFORMATION_SCHEMA.REPLICA_HOST_STATUS on each backend and looked for SESSION_ID=MASTER_SESSION_ID — that’s the only signal it uses to determine topology. It correctly placed the actual writer in HG 100 and the actual reader in HG 101, without any reconfiguration. Instance names in the AWS console are labels. Topology lives in REPLICA_HOST_STATUS.

Wiring ProxySQL to a production Aurora cluster?

There are more footguns in this setup than the docs let on — writer_is_also_reader constraints, domain_name leading-dot rules, query rule ordering when you have both local MySQL and Aurora backends active in the same ProxySQL instance. If you want a second pair of eyes on your configuration before it goes live, book a free assessment call.

Book Free Assessment →

Read/Write Split Smoke Test

Before triggering a failover, verify that query rules route correctly. Two checks: 50 SELECTs all land on the reader, and 5 INSERTs all land on the writer.

# -- 50 SELECTs through proxysql-1:6033 — expect all to hit HG 101 (Aurora reader)
for i in $(seq 1 50); do
  mysql -h 192.168.105.7 -P 6033 -u app -p'<password>' \
    -sN -e 'SELECT @@hostname;'
done | sort | uniq -c
     50 ip-10-1-X-X

All 50 returned the same internal hostname — the reader instance — with zero variance. The ^SELECT rule (rule_id 11) caught every query and sent it to HG 101.

# -- 5 INSERTs through proxysql-1:6033 — expect all to hit HG 100 (Aurora writer)
for i in $(seq 1 5); do
  mysql -h 192.168.105.7 -P 6033 -u app -p'<password>' \
    -sN -e "INSERT INTO failover_test (payload, hostname)
            VALUES ('write-test', @@hostname);"
done

# -- verify write routing: read the inserted rows back through the reader path
mysql -h 192.168.105.7 -P 6033 -u app -p'<password>' \
  -e "SELECT payload, hostname, COUNT(*) cnt
      FROM failover_test
      WHERE payload='write-test'
      GROUP BY hostname;"
payload     hostname         cnt
write-test  ip-10-1-X-XXX      5

The INSERT wrote @@hostname — the current backend’s internal IP — directly into each row. The follow-up SELECT (routed to the reader via the ^SELECT rule) read those rows back and confirmed: all five writes landed on ip-10-1-X-XXX, the writer instance, and replicated to the reader. This pattern — write a value, read it back through the proxy’s reader path — verifies routing end-to-end, not just that ProxySQL parsed the query rule correctly. It confirms the write actually reached the writer and that the reader returned the replicated result. Use it whenever you need to validate routing through the full path rather than by inspecting ProxySQL internals alone.

Failover Under Load: The Timeline

Setup

A Python script ran 10 SELECTs per second through proxysql-1:6033, logging each result with a UTC timestamp. Each SELECT routes to HG 101 (Aurora reader) via the ^SELECT rule.

#!/usr/bin/env python3
# -- load-generator.py — 10 SELECTs/sec through proxysql-1:6033
import subprocess, time, datetime

LOG = "/tmp/failover-traffic.log"
INTERVAL = 0.1  # 10 requests/sec

with open(LOG, "a") as f:
    while True:
        t = datetime.datetime.utcnow().isoformat(timespec="milliseconds")
        try:
            r = subprocess.run(
                ["mysql", "-h", "192.168.105.7", "-P", "6033",
                 "-u", "app", "-p<password>",
                 "--connect-timeout=3", "-e", "SELECT @@hostname;"],
                capture_output=True, text=True, timeout=5
            )
            status = (r.stdout.strip().split()[-1]
                      if r.returncode == 0
                      else f"ERR:{r.stderr.strip()[:60]}")
        except subprocess.TimeoutExpired:
            status = "TIMEOUT"
        f.write(f"{t} {status}\n")
        f.flush()
        time.sleep(INTERVAL)

Trigger

One command. T0 is the moment the API call returned:

# -- trigger Aurora cross-AZ failover — T0 = API accepted
aws rds failover-db-cluster --db-cluster-identifier proxysql-aurora-EXAMPLE

The Timeline

Marker   Elapsed    Event
------   -------    -----
T0       +0.0s      failover-db-cluster API accepted
—        +9.8s      Aurora: "Started cross AZ failover to proxysql-aurora-EXAMPLE-writer"
T1       +10.2s     First application error (connection timeout at ProxySQL)
T2       +10.3s     Last application error — total error window: 0.1s
T3       +15.3s     Queries resume through ProxySQL (new writer now accepting connections)
—        +18.0s     monitor.mysql_server_aws_aurora_log: first successful poll
                    showing new writer (SESSION_ID=MASTER_SESSION_ID flipped)
T4       +19.1s     runtime_mysql_servers updated — HG 101 now routes to new reader
—        +21.4s     Aurora: "Completed customer initiated failover"
—        +44.0s     Cluster status: available

Total application-visible errors: 2. Both within the same 0.1-second window at T1–T2. The remaining 1,483 queries ran without error.

ProxySQL Ahead of AWS

PROXYSQL UPDATED BEFORE AURORA DECLARED COMPLETE: ProxySQL updated its hostgroup topology at T0+19.1s. Aurora declared the failover complete at T0+21.4s. ProxySQL knew the topology had changed 2.3 seconds before Aurora’s own completion event arrived. It doesn’t wait for AWS — it reads REPLICA_HOST_STATUS directly, on its own polling schedule, on every cycle regardless of what Aurora’s control plane is doing.

What the 6-Second Gap Actually Means

The monitor log shows exactly what happened between T1 and T3:

-- monitor.mysql_server_aws_aurora_log — failover detection window
-- Rows filtered to MASTER_SESSION_ID (writer-identifying polls only)
check_utc               hostname (polled)                                    writer_detected
2026-05-08 10:53:06     proxysql-aurora-EXAMPLE.cluster-EXAMPLE-SUFFIX...   proxysql-aurora-EXAMPLE-reader  ← last pre-failover confirmation
2026-05-08 10:53:10     proxysql-aurora-EXAMPLE-reader.EXAMPLE-SUFFIX...    proxysql-aurora-EXAMPLE-reader  ← last poll before the gap

  [gap: 10:53:10 → 10:53:16]
  [Aurora mid-promotion — backends temporarily unreachable]
  [ProxySQL continued polling on schedule; all attempts failed to connect]

2026-05-08 10:53:16     proxysql-aurora-EXAMPLE-writer.EXAMPLE-SUFFIX...    proxysql-aurora-EXAMPLE-writer  ← new writer detected

The 6-second gap between 10:53:10 and 10:53:16 was not ProxySQL skipping polling cycles. ProxySQL was polling on schedule — check_interval_ms=2000 means it attempted a connection every 2 seconds — but Aurora’s backends were temporarily unreachable while the promotion was in progress. The endpoints went dark during the promotion and became reachable again once Aurora finished. ProxySQL detected the topology change on its first successful poll after Aurora’s internal promotion completed.

The correct model for detection latency:

detection latency = (Aurora internal promotion time)
                  + (at most one check_interval_ms cycle)

In this lab: approximately 6 seconds of Aurora internal promotion time, plus up to 2 seconds of polling lag, equals roughly 6–8 seconds from when Aurora initiated the promotion to when ProxySQL first read the new topology successfully. Lowering check_interval_ms from 2000ms to 500ms would not have produced 4× faster detection here. It would have shaved at most 1.5 seconds off the lag above the promotion floor. The floor is Aurora’s promotion time — that’s opaque to ProxySQL and set by instance class, workload, and cross-AZ replication state. Part 5 covers production sizing of check_interval_ms with that constraint in mind.

Post-Failover State

At T0+44s, runtime_mysql_servers on proxysql-1 shows the fully inverted topology:

-- runtime_mysql_servers on proxysql-1 (post-failover, T0+44s)
hostgroup_id  hostname                                                          port  status
100           proxysql-aurora-EXAMPLE-writer.EXAMPLE-SUFFIX.us-east-1...        3306  ONLINE  (new writer)
101           proxysql-aurora-EXAMPLE-reader.EXAMPLE-SUFFIX.us-east-1...        3306  ONLINE  (new reader)
101           proxysql-aurora-EXAMPLE.cluster-EXAMPLE-SUFFIX.us-east-1...       3306  ONLINE  (seed — still present)

HG 100 now holds the promoted instance. HG 101 holds the demoted instance plus the cluster endpoint seed (which now resolves to the new writer, but is still valid for read traffic in HG 101 since all ONLINE instances in a reader hostgroup are eligible).

The 60-Second Baseline Revisited

Part 1 described roughly 60 seconds of pain using the Aurora reader endpoint alone — stale DNS TTLs, connection pool churn, reads landing on a replica still behind the new writer’s binlog position. That figure was conservative for the reader endpoint under realistic production conditions: JVM DNS caching, long keepalive intervals, and a connection pool configured for throughput rather than fast reconnect after a backend change.

What ProxySQL changed: instead of waiting for DNS propagation, ProxySQL polls REPLICA_HOST_STATUS directly and reroutes at the TCP connection level. There’s no DNS layer between ProxySQL and Aurora’s instance endpoints. Application clients connected to proxysql-1:6033 stayed connected to ProxySQL throughout the failover — they never saw the backend change. The 2 errors we recorded were connection timeouts during the brief promotion window when no backend was reachable. Not stale-read errors, not reconnection storms, not silent misrouting. Two timeouts in a 0.1-second window, then normal operation resumed.

What’s Not in This Part

This part covers one thing: wiring ProxySQL to Aurora and verifying the configuration survives a live failover. Three topics are deferred by design:

  • Query routing depth — regex anatomy, rule priority ordering, per-user and per-schema routing, transaction_persistent behavior under mixed read/write workloads → Part 3
  • ProxySQL Cluster sync — how the two-node pair propagates Aurora hostgroup rules, what syncs automatically at runtime versus what requires manual intervention on new nodes → Part 4
  • Monitoring and tuning — querying mysql_server_aws_aurora_log in production, sizing check_interval_ms based on observed promotion time, alerting on detection gaps → Part 5

What’s Next

In Part 3, we wire the query routing layer. The cluster is connected and survives a failover — now we make the routing configuration production-grade. That means mysql_query_rules in depth: regex ordering, per-user routing, per-schema routing, and transaction_persistent behavior under sessions that mix reads and writes. If your ORM doesn’t always mark transactions explicitly, Part 3 is where the routing gets genuinely interesting.

M

Mario — ReliaDB

ReliaDB is a specialist DBA team for PostgreSQL and MySQL performance, high availability, and cloud database optimization. More about ReliaDB →

Planet for the MySQL Community